Google Search can continue displaying information about a deleted or unavailable webpage because search indexing is separate from the live website. Persistent ghost results generally occur when Google has not yet processed the page’s changed status, retained URL signals, or refreshed its indexed representation.
Reputation management strategies differ based on whether the objective involves removing an underlying source, reducing its search visibility, or strengthening alternative content. Online reputation control methods are evaluated through search visibility, reputation signals, entity credibility, search ranking influence, and the durability of the resulting SERP composition.
How Does Google Search Caching Differ From Search Indexing?
Google Search caching and indexing represent different mechanisms, with indexing determining whether information is available for retrieval and caching historically representing a stored version of page content. A search index records information Google has processed about URLs, documents, entities and relationships, while a cached representation concerns previously retrieved content rather than the current state of the website. A page therefore does not disappear from search merely because its live HTML has been removed. Googlebot needs to revisit the URL and process the resulting response before the index reflects the changed state. This distinction explains why a deleted page can produce a ghost result after the source has already disappeared. From a reputation perspective, the underlying issue is persistent search visibility rather than conventional browser caching.
A persistent ghost result is an indexed search reference that remains visible after the corresponding source content has changed or disappeared. It operates through retained URL-level information, historical indexing signals and delayed processing of the latest crawl state. The result can contain an old title, outdated description or other information even when the destination no longer provides the original content. Search ranking systems evaluate available indexed information rather than continuously reproducing every website’s current state. Consequently, removing a webpage and removing its search representation are separate events. Effective evaluation therefore begins by identifying which layer of the search ecosystem still contains the unwanted information.
Which Fix Works Better: Removing the Source or Removing Search Visibility?
Removing the source addresses the underlying content, while search visibility controls address how that content appears within search results. A permanent source removal generally relies on the URL returning an appropriate HTTP response, such as 404 Not Found or 410 Gone, rather than continuing to serve the original material. Search engines can then recognise that the document is no longer available and progressively update their indexes. Search-result removal mechanisms address a different layer because they concern the visibility of qualifying information in search rather than the existence of the source itself. The two approaches therefore operate at different points in the information retrieval process. Evaluation depends on whether the objective is permanent source correction, search-result suppression, or both.
Source removal has greater relevance when the website owner controls the underlying page because it changes the canonical availability of the information. Search-result mechanisms have greater relevance when the source remains accessible but specific information qualifies for removal under applicable policies or legal frameworks. Neither mechanism automatically guarantees that equivalent information disappears from other websites, URLs or search engines. Reputation signals remain distributed across independent sources, meaning one successful removal does not necessarily eliminate the broader digital footprint. This creates an important distinction between content suppression and content elimination. Search visibility therefore requires evaluation across both source-level and index-level conditions.
Is Content Removal More Effective Than Content Creation for Reputation Repair?
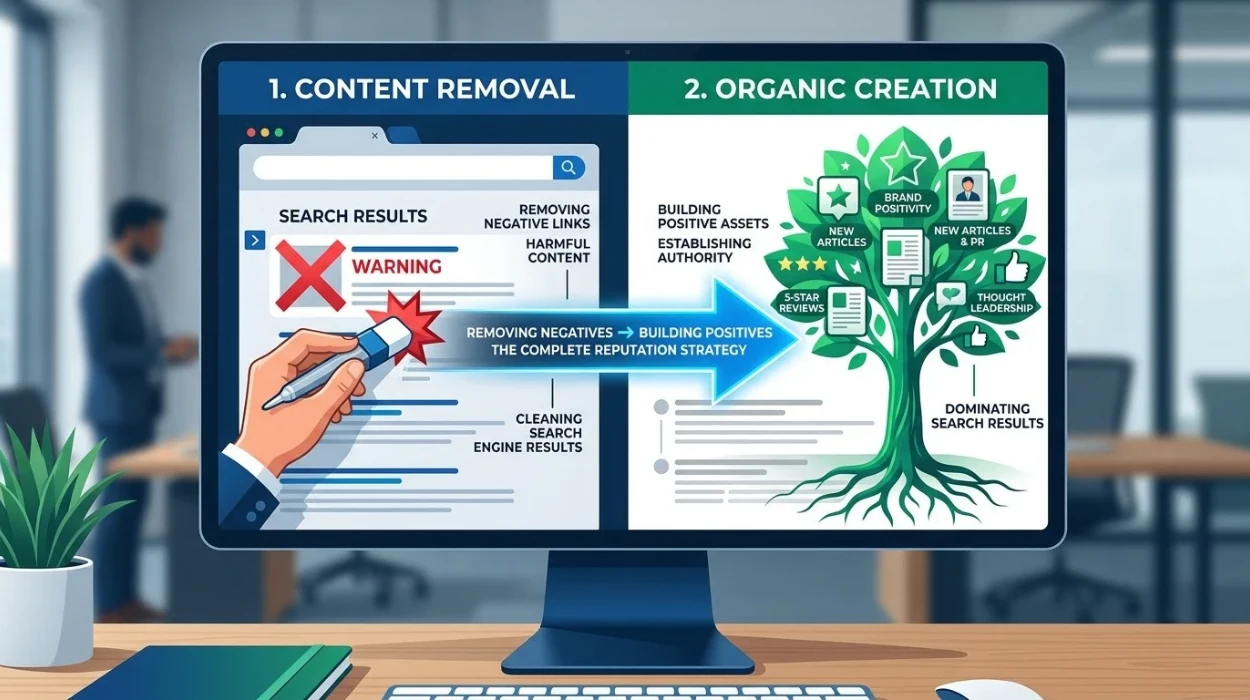
Content removal and content creation solve different reputation problems, so effectiveness depends on the nature and persistence of the negative search signal. Removal strategies target an existing source that creates an unwanted association, while content creation introduces additional relevant documents that can influence SERP composition. A removal strategy operates by changing the availability or search eligibility of a specific document. A content enhancement strategy operates by increasing the relevance, quality and authority of alternative information around the same entity. The first approach addresses an existing signal directly, while the second changes the competitive composition of the search results. Comparing them therefore requires measuring the source’s authority, query relevance, persistence and position within the SERP.
Content creation offers a scalable method for establishing a broader information environment around an entity, but its impact depends on search ranking influence and competing source strength. New content does not automatically displace an established result, particularly where the existing source has strong authority, substantial links or high query relevance. Removal can produce a more direct change when the underlying content qualifies for deletion or deindexing, but it is constrained by ownership, eligibility and procedural requirements. Enhancement is therefore expansive but competitive, whereas removal is direct but conditional. Reputation management analysis treats these differences as strategic variables rather than assuming one universal solution. The resulting SERP composition reflects the interaction between source authority, relevance, freshness and other ranking signals.
How Do Organic and Reactive Reputation Strategies Compare?
Organic reputation management builds a favourable information environment continuously, whereas reactive management responds to a specific negative or inaccurate search result. Organic methods operate through sustained publication, accurate entity information, authoritative references and consistent digital presence. Reactive methods operate through source correction, removal requests, legal processes, technical remediation or targeted search-result measures. Organic activity can influence sentiment distribution over time because it increases the volume and relevance of information associated with an entity. Reactive activity focuses on a defined source or search-result problem and therefore has a narrower operational scope. The distinction becomes important when evaluating whether a reputation issue is isolated or represents a broader weakness in digital information coverage.
Reactive strategies offer a clearer connection between an identified problem and a defined intervention, but their sustainability depends on the underlying source and applicable removal mechanism. Organic strategies provide continuing reputation signals but require ongoing content governance and do not guarantee displacement of authoritative negative material. A balanced evaluation therefore measures both immediate visibility changes and longer-term SERP stability. Short-term suppression concerns whether a result becomes less visible after intervention, while long-term control concerns whether the search environment remains resilient when indexes refresh. This distinction prevents temporary changes from being treated as permanent reputation improvements. The strongest assessment separates immediate search effects from durable changes to the digital footprint.
How Can Persistent Ghost Results Be Evaluated Before Choosing a Fix?
Persistent ghost results require technical and search-level assessment before an intervention is selected. The first evaluation identifies whether the URL remains live, redirects elsewhere, returns a 404 or 410 response, or presents substantially different content. The second evaluates whether Google still indexes the URL and whether the displayed title or snippet reflects historical information. The third examines whether duplicate URLs, syndicated copies or related pages reproduce the same reputation signal. The fourth measures the result’s search position, query relevance and source authority. The fifth assesses whether the issue affects one URL or represents a wider entity-level visibility problem.
A practical evaluation framework can therefore be structured around distinct evidence points:
- Inspect the source URL and record its current HTTP status to establish whether the underlying document remains available.
- Compare the live page with the displayed search snippet to identify outdated titles, descriptions or historical content.
- Measure the result’s ranking position and query relationship to determine its actual search visibility.
- Identify duplicate or syndicated sources to establish whether removal from one URL leaves equivalent information elsewhere.
- Assess entity associations and sentiment distribution to determine whether the result represents an isolated document or a broader reputation signal.
This process distinguishes technical persistence from reputational persistence. A deleted URL that remains indexed represents an indexing problem, while equivalent negative information appearing across active sources represents a broader SERP composition problem. The distinction affects scalability because individual URL remediation becomes less efficient when the same signal exists across numerous domains. Risk exposure also differs because removal requests depend on specific eligibility criteria, while content enhancement depends on ranking competition. Measurement therefore needs to track both the target result and the wider search landscape.
Dive Deeper With Our Expert Guides:
What the Most Effective Routes Are for Getting a Google Image Removed in the UK
How to Request Google Cache Removal in the UK and What the Process Involves
What Is the Difference Between Short-Term Suppression and Long-Term Search Control?
Short-term suppression reduces the immediate visibility of a particular search result, while long-term search control focuses on the stability of the overall information environment. Suppression operates through mechanisms that limit a URL’s appearance under qualifying circumstances or accelerate the processing of changed content. Long-term control operates through sustained source management, authoritative content development and consistent entity information. A temporary reduction in visibility does not establish that the underlying digital footprint has changed permanently. Search indexes are continuously refreshed, and new pages can introduce competing information into the SERP. Long-term evaluation therefore measures persistence across repeated search cycles rather than relying on a single result-page observation.
The sustainability of each approach depends on the cause of the ghost result. A technically deleted page with a persistent index entry has a different remediation pathway from an active webpage containing disputed information. A source that repeatedly republishes removed material also creates a different risk profile from a single outdated URL. Search perception is consequently shaped by both technical availability and information repetition. Entity credibility depends on the consistency and authority of information surrounding the entity rather than one isolated ranking position. Strategic assessment must therefore distinguish between removing a document, suppressing a result and strengthening the wider information environment.
How Do Search Engines Interpret Reputation Signals After Content Changes?
Search engines interpret reputation signals through information associated with entities, documents, queries and sources rather than through a single reputation score. Search ranking influence emerges from relationships between relevance, authority, content quality, user intent and other signals used to determine which documents appear for a query. When a page disappears, the search system needs to process the changed source state before its representation is updated. When replacement content appears, that content enters the ranking environment and competes according to its own relevance and authority. This means deleting one result does not automatically transfer its previous ranking position to another document. The SERP is reconstructed from the information available to the search system.
For reputation analysis, sentiment distribution describes how positive, neutral and negative information is represented across relevant search results. Entity credibility concerns whether authoritative sources consistently identify and describe the same entity without confusing or contradictory associations. Search visibility measures how frequently and prominently relevant information appears for defined queries. These concepts interact but remain distinct, making measurement more reliable when each is tracked separately. Content suppression changes the availability or visibility of a signal, while content enhancement changes the surrounding information set. A complete assessment therefore examines both mechanisms rather than treating search reputation as a single ranking metric.
Which Approach Provides the Most Sustainable Response to Ghost Results?
Sustainability depends on whether the intervention resolves the cause of persistence rather than only changing the visible search result. Source-level correction provides a durable basis when a webpage has genuinely been removed and the technical status communicates that change correctly. Search-result mechanisms provide a targeted response when information meets the relevant removal criteria but remains available at its source. Content enhancement provides longer-term environmental change by establishing additional authoritative information, although ranking competition remains a continuing variable. These approaches address different failure points and therefore cannot be treated as interchangeable. The appropriate comparison considers effectiveness, scalability, risk exposure and maintenance requirements together.
A robust reputation management strategy separates immediate remediation from long-term information governance. Immediate remediation focuses on the specific URL, search representation and technical status responsible for the ghost result. Long-term governance focuses on authoritative sources, entity consistency, content quality and the distribution of relevant information across search results. This separation prevents a temporary SERP change from being interpreted as complete reputation repair. It also clarifies when content removal is appropriate and when content enhancement addresses the broader problem more effectively. Where a qualifying dead or unavailable source remains persistently visible, a Dead Link Removal Service represents one potential service category within the wider set of removal and search-visibility mechanisms, without replacing the need for technical assessment.
What Should Be Considered Before Selecting a Ghost Result Remediation Method?
The most useful evaluation considers the source status, search visibility, eligibility for removal, authority of competing sources and expected durability of the intervention. Technical remediation addresses whether the original URL has actually been removed, while search remediation addresses whether its representation continues appearing in search. Content enhancement addresses the wider SERP environment and the availability of authoritative alternative information. Risk assessment considers whether an intervention is supported by applicable policies, ownership rights or other recognised grounds. Scalability considers whether the same method remains practical across one URL or a large collection of sources. Sustainability measures whether the result remains resolved after subsequent crawling and indexing cycles.
The central distinction is between changing a webpage and changing its search representation. A deleted page can persist as a ghost result because search indexing operates independently from the website’s current presentation. Removal, suppression and enhancement each influence different components of the search ecosystem, producing different effects on visibility and reputation signals. Short-term interventions focus on immediate SERP changes, while sustainable strategies examine the underlying digital footprint and information distribution. A precise evaluation therefore avoids assuming that one mechanism resolves every type of persistent result. The appropriate approach is determined by the source condition, search behaviour, evidence and intended duration of the change.
Google ghost results are best understood as an indexing and search-visibility issue rather than ordinary browser caching. Source removal changes the availability of the original document, search-result mechanisms address qualifying visibility, and content enhancement changes the surrounding SERP composition. Organic strategies build reputation signals progressively, while reactive strategies address defined search problems. Short-term suppression measures immediate visibility, whereas long-term control evaluates persistence, entity credibility and the broader digital footprint. Comparing these mechanisms through effectiveness, scalability, risk exposure and sustainability provides a clearer basis for selecting an appropriate remediation pathway. The key consideration is whether the intervention addresses the source itself, its representation in search, or the wider information environment influencing search perception.
How does Google Search caching work?
Google Search caching refers to stored or indexed versions of web content that can continue influencing search results after a page changes or disappears. Search engines periodically recrawl and update their indexes, so outdated information may remain visible temporarily.
Why do ghost results appear in Google Search?
Ghost results can occur when Google continues displaying information from an older indexed version of a webpage, even after the original content has been removed or changed. Cached references, snippets, indexing delays and third-party pages can all contribute to persistent search results.
How can I remove an outdated Google Search result?
The appropriate removal method depends on whether the source page has been deleted, updated, or remains online. Google offers removal processes for certain outdated, private or policy-violating content, while source-level removal may be necessary when the underlying webpage is still accessible.
How long does it take for Google to remove a persistent search result?
The timeframe varies depending on the removal method, the source website and Google’s crawling and indexing processes. Removing content from the original webpage can help, but search results may continue appearing until Google processes the updated source.
Can Clear Your Name help with persistent ghost results in Google?
Clear Your Name addresses search visibility and online reputation issues involving persistent or outdated information in search results. The appropriate approach depends on the source, the nature of the content and whether removal, de-indexing or another search-result management method applies.