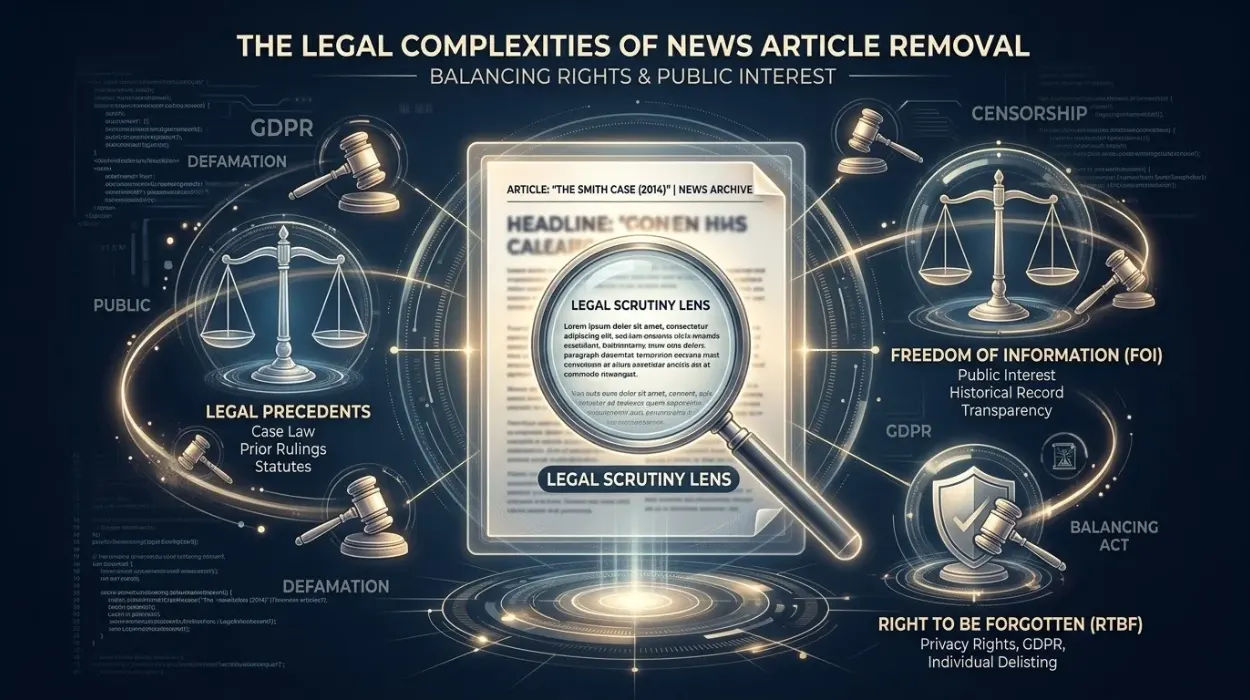
A news website can be legally required to remove or amend an old article in specific circumstances, but there is no general right to force removal simply because the article is outdated or damaging to reputation.
Reputation management is the process of understanding and influencing how information about a person, organisation, or entity is represented across digital environments, including search results.
Online reputation refers to the way publicly available information contributes to perceived credibility and entity perception within search ecosystems. An old news article forms part of a digital footprint when search engines continue to index, rank, and associate it with a person’s name, organisation, or other identifiable entity. The legal position depends on the nature of the information, its accuracy, the circumstances in which it was published, applicable privacy rights, and the jurisdiction governing the publication. Search visibility therefore involves two connected systems: the publisher’s control over the original content and the search engine’s process for indexing and ranking that content.
Can an old news article be legally removed from a website?
An old news article is not automatically unlawful because it remains online after the event it describes has become outdated. News publishers generally retain editorial control over archival material, particularly where the article accurately reported information that was lawful to publish when released. Legal removal therefore depends on a specific legal basis rather than the age of the article itself.
The distinction between outdated information and unlawful information is important for reputation analysis. An article can remain factually accurate while becoming less relevant over time, creating a difference between historical accuracy and present-day relevance. Search engines can continue indexing the page because the underlying content remains available and technically accessible. This creates a reputation signal that reflects both the original reporting and the continuing accessibility of the information.
A legal request becomes more substantial when identifiable legal rights are engaged. Depending on the circumstances, relevant issues include defamation, privacy, data protection, copyright, court restrictions, or demonstrable factual inaccuracies. Each legal basis operates through different rules, so an argument based solely on reputational harm does not establish an automatic entitlement to removal.
Does the age of a news article create a right to have it removed?
The age of an article alone does not create a universal legal right to deletion. Historical reporting can remain part of a publisher’s archive even when the subject considers the information no longer relevant. The legal analysis instead examines the content, context, continued publication, and rights affected by its availability.
From a search perspective, age also does not automatically eliminate visibility. A page that has accumulated backlinks, publisher authority, references from other websites, and established indexing signals can continue appearing for relevant searches. Search ranking systems evaluate signals associated with relevance and authority rather than applying a simple rule that older pages disappear. Consequently, an article published years ago can remain part of an entity’s search profile.
Reputation analysis therefore separates publication age, legal validity, and search visibility. These are different properties of the same digital asset. An old article can be legally permissible, factually accurate, and highly visible at the same time. Understanding this distinction prevents search ranking behaviour from being confused with a legal obligation to remove content.
When can inaccurate information in a news article create legal issues?
Demonstrably false factual claims can create legal issues because accuracy is distinct from opinion, commentary, or historical reporting. The applicable legal route depends on the jurisdiction and the nature of the statement. In the UK, defamation law provides a framework for addressing published statements that satisfy the relevant legal requirements, while data protection law addresses a different category of information rights.
Accuracy also matters to search reputation because factual errors can become persistent reputation signals. Once indexed, an inaccurate statement can be reproduced through snippets, references, aggregators, social posts, or other websites. The original article therefore becomes part of a broader information network rather than functioning as an isolated page.
A factual correction does not necessarily produce the same technical outcome as deletion. A publisher can amend an article while retaining the page, adding a correction, updating contextual information, or changing the wording of the original report. Search engines then process the revised page through their normal crawling and indexing systems. This means editorial correction and search de-indexing are separate mechanisms.
What is the difference between removing an article and removing it from search results?
Article removal eliminates or changes the original publication on the publisher’s website, whereas search-result removal generally concerns the visibility of a URL in response to particular searches. These actions operate at different levels of the information ecosystem. Removing the source page affects the underlying content, while de-indexing affects how that content is retrieved through a search engine.
This distinction is fundamental to understanding search visibility. A page can remain accessible on the publisher’s website while becoming unavailable for particular name-based searches through a valid search-engine delisting process. Conversely, removing a source article can reduce the likelihood that search engines continue displaying that particular URL because the original page no longer exists.
Search engines therefore do not function as publishers in the same way as news websites. Their systems crawl, index, classify, and rank information obtained from external sources. A request concerning search visibility must consequently be directed towards the mechanism responsible for the specific form of visibility being challenged.
Does the UK right to be forgotten apply to old news articles?
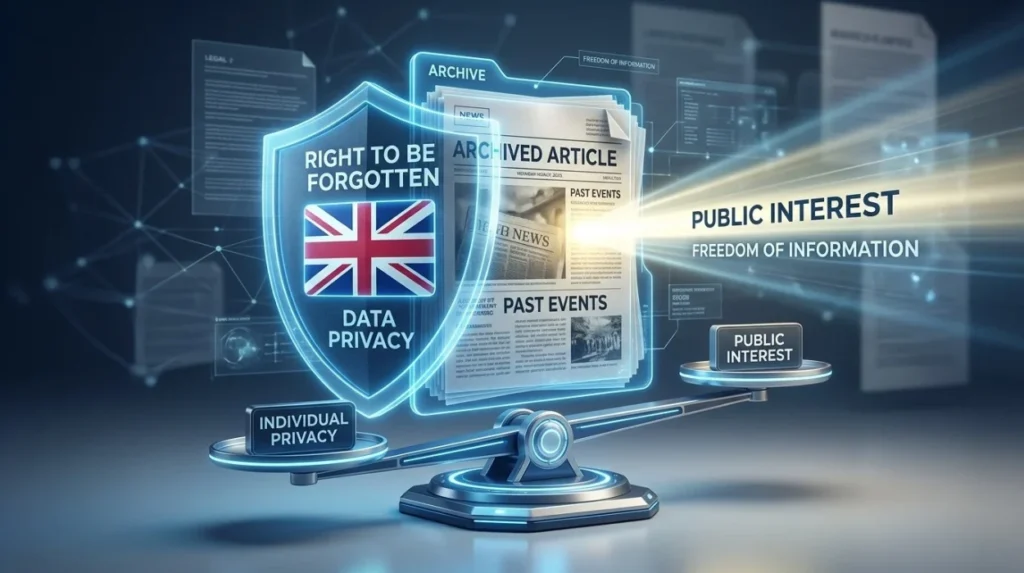
The UK data protection framework recognises rights relating to the processing of personal data, including circumstances in which an individual can request erasure or object to processing. These rights are not an unrestricted right to delete historical journalism. The application depends on the nature of the personal data, the purpose of processing, applicable exemptions, and the competing interests involved.
The concept commonly described as the right to be forgotten therefore requires careful distinction between source removal and search-result delisting. A search engine can be asked to consider whether particular results involving an individual’s name satisfy the relevant data protection requirements. The publisher’s underlying article remains a separate legal and technical issue.
This distinction affects entity perception in search results. A person can have an article remain within a publisher’s archive while the article receives reduced visibility for searches involving that person’s name. Search perception is consequently influenced by both source availability and retrieval mechanisms. Data protection rights address particular processing circumstances rather than establishing a general rule that old news disappears from the internet.
How do search engines evaluate old news content?
Search engines evaluate indexed content through systems that consider relevance, quality, authority, links, freshness, query context, and other signals. An old article does not automatically lose all ranking value simply because its publication date is distant. Its continued relevance to a search query and the authority of the publishing domain can contribute to sustained search visibility.
News content also receives contextual treatment because search engines need to distinguish current reporting from historical material. Publication dates, updated dates, structured data, links, topical relevance, and query intent contribute to how pages are interpreted. These mechanisms influence SERP evaluation without determining whether an article is legally permissible.
For reputation management, this means that search results represent an interpretation layer between the original publication and the user. The same article can have different visibility for different queries because search systems evaluate relevance in relation to the searcher’s wording and intent. Entity perception is therefore shaped not only by what information exists but also by how search systems retrieve and organise that information.
How do reviews and other reputation signals interact with news coverage?
Reviews contribute a separate category of reputation signal because they contain user-generated assessments rather than conventional editorial reporting. Search engines can interpret review-related information through structured review data, textual content, ratings, relevance, and the broader authority of the source. News coverage operates through different content and authority signals, although both can appear within the same branded or personal search environment.
Sentiment interpretation also differs from factual verification. A negative review expresses an assessment, while a news article can contain factual claims, quotations, analysis, or reporting. Search systems do not simply calculate a single universal reputation score from these sources. Instead, different information types contribute to the wider search environment surrounding an entity.
The resulting SERP can therefore contain news stories, review platforms, social profiles, directories, official websites, and other sources simultaneously. Each result provides a distinct reputation signal. Understanding this information architecture is essential because removing one URL does not necessarily remove every reference to the same information elsewhere.
What authority and trust signals affect the visibility of news articles?
Authority refers to the signals that help search systems assess the reliability and relevance of a source for a particular information need. A recognised news publisher can possess established domain-level signals, editorial history, external references, and links from authoritative websites. These factors can support continued visibility even when an individual article is old.
Trust signals operate across both content and source context. Search systems evaluate whether information is relevant, useful, consistent, and supported within the wider web environment. An article referenced by other credible sources can become embedded within a broader network of information, making its search presence less dependent on the original page alone.
This creates an important distinction between content authority and content accuracy. A highly authoritative publisher can still publish an article containing an error, while an accurate article from a less authoritative source can receive limited visibility. Reputation analysis therefore evaluates the specific information, its source, its relationships with other entities, and its position within search results.
Dive Deeper With Our Expert Guides:
Why News Articles About You Can Stay Online for Decades Without Intervention
Why Old News Articles Continue to Harm Reputations Long After the Story Fades
What happens when a news website refuses to remove an article?
A refusal to remove an article does not necessarily determine whether the underlying legal issue has been resolved. A publisher can reject a removal request because it considers the article accurate, editorially justified, legally protected, or outside the requested remedy. The appropriate response depends on the legal basis supporting the request and the mechanism being challenged.
From a search perspective, the publisher’s decision and search engine’s decision remain separate. A person can challenge the publication itself, the processing of personal information, or the article’s appearance in particular search results depending on the circumstances. Each route requires different evidence and addresses a different part of the information system.
The distinction also demonstrates why reputation analysis requires more than assessing whether a page is negative. The relevant questions concern what the content states, whether the statement is factual or opinion-based, whether it is accurate, what legal rights apply, where the information is published, and how it is indexed. These factors define the available mechanisms without assuming that removal is legally available.
How does an old news article affect online reputation?
An old article affects online reputation when its information continues to form part of the searchable record associated with an individual, organisation, or other entity. Its impact depends on its content, ranking position, query relevance, source authority, and relationship with other information. A page appearing prominently for an entity-related search has greater visibility than an inaccessible or poorly ranked archival page.
The digital footprint created by historical reporting is cumulative. Search engines connect names, organisations, events, websites, locations, topics, and other identifiable entities through information relationships. An old article can therefore remain relevant to entity perception even when the underlying event is no longer current.
Reputation management is consequently concerned with understanding how information accumulates and is interpreted across search ecosystems. It does not treat every negative result as equivalent or assume that every unwanted page has the same legal status. Instead, it analyses publication, indexing, ranking, authority, accuracy, privacy, and context as distinct components of online credibility.
What should be examined before deciding whether an article can be challenged?
The first step is to identify the exact content and the mechanism producing the concern. A legal challenge requires analysis of the statement, publication circumstances, jurisdiction, applicable rights, and available remedies. A search visibility issue requires additional analysis of indexing, query relevance, ranking position, and the search engine involved.
A structured assessment can examine the following elements:
- Identify the claim — determine whether the disputed material contains a factual assertion, opinion, quotation, or historical record because each category receives different treatment.
- Verify the information — compare the published claim with reliable evidence because demonstrable inaccuracies create a different issue from information that remains factually supported.
- Assess the legal basis — determine whether defamation, privacy, data protection, copyright, or another applicable rule provides a recognised route for challenging the material.
- Evaluate search visibility — examine the article’s indexed URLs, ranking positions, snippets, and related results because source publication and SERP visibility are separate mechanisms.
- Map related reputation signals — identify reviews, references, profiles, directories, and other indexed sources because removing one page does not necessarily remove associated information from the wider digital footprint.
This process separates legal entitlement from search perception. It also prevents the age of an article, its negative tone, or its ranking position from being treated as sufficient evidence of a legal right to removal.
How do article removal and the right to be forgotten differ?
Article removal concerns the original publication, while the right to be forgotten generally concerns particular processing or search-result visibility involving personal information. The two mechanisms therefore address different layers of the information ecosystem. Understanding that distinction is essential when analysing whether an old news article can be challenged.
The legal and technical outcome depends on the specific facts. A publisher can retain an article while a search engine changes how it appears for a particular individual’s name. Alternatively, a publisher can correct or remove an article while references to the same information remain available elsewhere. These outcomes demonstrate why content indexing and source publication must be analysed separately.
News Article Removal vs. Right to Be Forgotten: Which Applies to Your Case? can therefore be understood as a distinction between source-level intervention and search-level or data-processing rights. The appropriate mechanism depends on the legal basis, information involved, publisher, search engine, jurisdiction, and requested remedy.
What is the key principle behind challenging an old news article?
The key principle is that an old article does not become legally removable solely because it is old, negative, or visible in search results. Legal rights depend on defined grounds, while search visibility depends on indexing and ranking systems. These mechanisms must be assessed independently.
Online reputation refers to the searchable information environment through which an entity is represented and interpreted. News articles, reviews, authoritative references, social profiles, and other digital assets collectively contribute to that environment. Understanding how each source is created, indexed, evaluated, and displayed provides a more accurate framework for analysing reputation signals.
The distinction between legal removal, editorial correction, data protection rights, and search-result delisting is therefore central to understanding digital reputation. A source can remain historically available while its search visibility changes, and a removed source can leave related information elsewhere in the digital footprint. Reputation analysis begins by identifying which layer of the information ecosystem is responsible for the issue and which mechanism governs that layer.
Can you legally force a news website to remove an old article?
An old news article cannot usually be removed simply because it is outdated or damaging to your reputation. Removal depends on factors such as factual inaccuracies, defamation, privacy rights, data protection law, or another recognised legal basis.
Can a news website refuse to take down an old article?
Yes, a news website can refuse a removal request when it considers the article accurate, lawful, and editorially justified. The available options depend on the legal grounds for challenging the publication and the jurisdiction involved.
Does the right to be forgotten apply to old news articles?
The right to be forgotten can apply to certain personal information appearing in search results, but it does not provide an automatic right to delete historical journalism. Its application depends on data protection requirements, the information involved, and competing rights such as freedom of expression.
What is the difference between news article removal and search-result removal?
News article removal affects the original content published on a website, while search-result removal affects how a URL appears for particular searches. These are separate processes because deleting a source page and changing search visibility involve different mechanisms.
Can Clear Your Name help with old news article removal?
Clear Your Name focuses on issues involving unwanted online information, including article removal and related reputation concerns. The appropriate approach depends on whether the content involves legal grounds for removal, factual inaccuracies, privacy issues, or search visibility rather than simply its age.