Digital copyright infringement in online search results occurs when protected creative content is reproduced, distributed, displayed, or made available without the rights holder’s authorisation. Reputation management is the structured process of understanding and influencing how information about an entity is represented across digital environments. Online reputation refers to the cumulative perception formed from indexed content, search results, reviews, references, and other reputation signals associated with an individual, organisation, or brand.
What Is Digital Copyright Infringement in Search Results?
Digital copyright infringement is the unauthorised use of copyright-protected material in a digital environment. Copyright generally protects original expression rather than ideas, facts, methods, or concepts, with the precise scope depending on the applicable legal framework. In search ecosystems, infringement becomes relevant when protected material appears on a website, is reproduced within indexed content, or is presented through another digital resource without the necessary rights or legal basis. Search engines primarily organise and retrieve online information, so the existence of a copyrighted work in search results does not automatically establish that the search engine itself infringes copyright. The distinction between the underlying content and its appearance within a SERP is therefore essential for accurate evaluation.
How Does Copyrighted Content Enter Online Search Results?
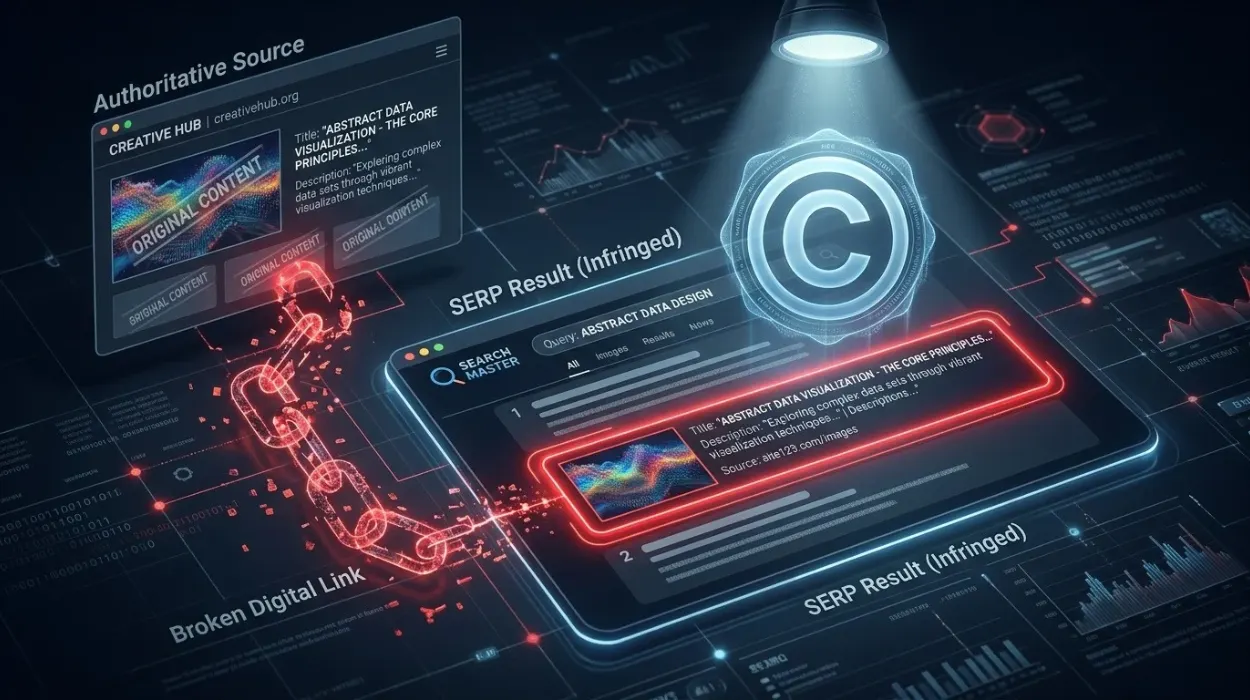
Copyrighted content enters search results when search engines discover, crawl, index, and rank webpages containing that material. Content indexing creates a searchable representation of information available on publicly accessible webpages, while ranking systems determine which indexed pages receive visibility for particular queries. An unauthorised copy can therefore become part of the searchable information environment when a webpage containing it is accessible to search-engine crawlers. Search visibility does not itself establish ownership, permission, or infringement because those questions depend on the underlying content and rights involved. The search result functions as a discovery mechanism that connects users with the webpage hosting the relevant material.
What Types of Online Content Can Be Protected by Copyright?
Copyright can protect original creative expression such as written articles, photographs, illustrations, graphics, videos, music, software code, and other qualifying works. Protection attaches to the original expression rather than the general subject matter, factual information, or underlying idea. This distinction affects how content appearing in search results is evaluated because copying a protected article differs from independently reporting the same factual information. A webpage containing factual information can also contain separately protected expressive elements, such as its wording, photographs, or original graphics. Reputation analysis therefore requires examination of the specific material allegedly copied rather than treating every similarity between two webpages as infringement.
How Do Search Engines Evaluate Copyrighted Content?
Search engines evaluate webpages through automated systems that analyse factors associated with crawling, indexing, relevance, quality, and search visibility. These systems are designed primarily to retrieve useful information for a query rather than determine ownership of every piece of content appearing online. Search engines can therefore index pages containing material that is disputed, duplicated, or allegedly unauthorised without making a legal determination about the material. Copyright complaints operate through separate reporting and legal-policy processes that address particular allegations. This distinction separates SERP evaluation from copyright adjudication and prevents search ranking from being interpreted as proof of legal legitimacy.
How Does Duplicate Content Affect Search Visibility?
Duplicate content refers to substantially similar or identical material appearing across more than one webpage or digital location. Search engines can identify relationships between similar pages and select which version or source receives stronger visibility for a particular query. This process concerns information organisation and search retrieval rather than automatically determining which party legally owns the material. A copied article can therefore affect the original publisher’s search environment even when the ranking system has not established that copying occurred unlawfully. Duplicate-content analysis is consequently a search visibility issue, while copyright analysis focuses on ownership, protected expression, authorisation, and applicable legal exceptions.
How Do Copyright Issues Affect Online Reputation?
Copyright disputes can affect online reputation when disputed content becomes visible for searches associated with an individual, organisation, product, or other identifiable entity. Search results contribute to entity perception because users frequently encounter indexed webpages before interacting directly with the underlying organisation or person. A webpage containing unauthorised material can also reproduce inaccurate, incomplete, or contextually misleading information, creating an additional reputation signal. The reputational effect depends on factors including the content itself, its search position, query relevance, source authority, and how users interpret the result. Copyright analysis therefore intersects with reputation management when intellectual-property disputes influence the information environment surrounding an entity.
What Role Do Authority and Trust Signals Play in Copyright-Related Search Results?
Authority and trust signals influence how webpages are interpreted within search ecosystems, but they do not establish copyright ownership. Search systems analyse signals associated with a source’s relevance, authority, quality, and relationship to a search query when determining visibility. Users also interpret source credibility through recognisable publishers, contextual information, publication details, and consistency across indexed references. A webpage from an authoritative domain can therefore receive substantial visibility even when the underlying content is disputed. Copyright status remains a separate legal question that requires analysis of the protected work, ownership, authorisation, and applicable law.
How Can Someone Distinguish Copyright Infringement From Legitimate Content Use?
Copyright infringement cannot be established solely because two online pages contain similar information. The assessment requires identifying the protected work, determining the relevant rights holder, examining what material was reproduced, and considering whether permission, licensing, an exception, or another legal basis applies. The jurisdiction also matters because copyright rules differ between legal systems and specific uses can receive different treatment. Search visibility provides evidence about where information appears, but it does not independently resolve the underlying copyright question. Accurate evaluation therefore separates factual evidence about content from legal conclusions about whether its use is authorised.
Content removal and search delisting address different locations within the information ecosystem. Content removal targets the webpage, hosted material, publication, or other original source, while search delisting targets the visibility of a result within a particular search service. Removing an article from its source can affect the underlying content itself, whereas delisting generally concerns whether a search engine displays a result for specified queries. These mechanisms therefore have different effects on content indexing and search visibility. A person assessing a copyright-related reputation issue needs to identify whether the underlying problem concerns the source content, its distribution, its search visibility, or a combination of these factors.
What Evidence Helps Document Possible Copyright Infringement?
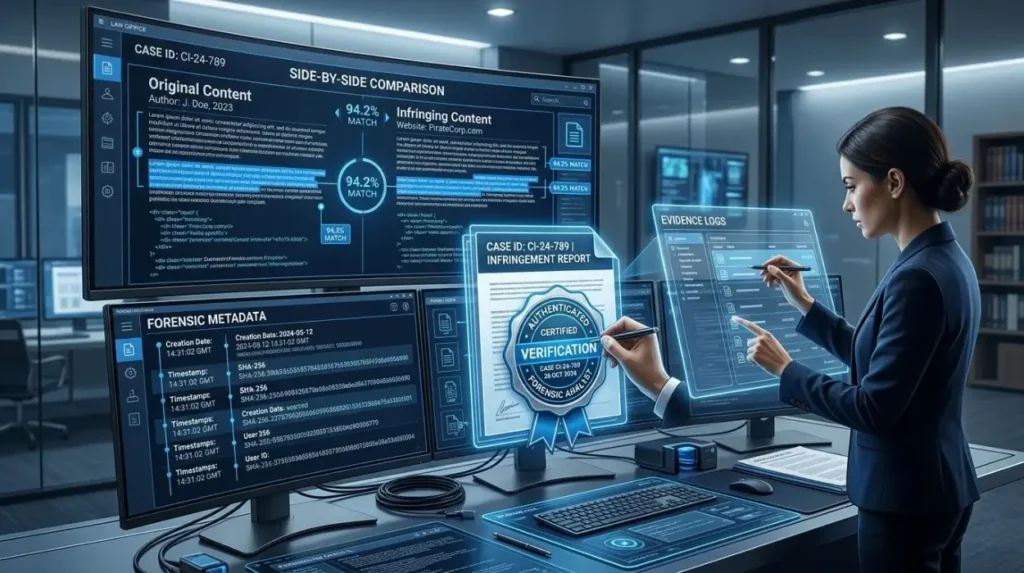
Evidence establishes the relationship between the original work, the allegedly unauthorised use, and the location where the disputed material appears. Effective documentation focuses on identifiable facts rather than assumptions about intent or motive.
- Identify the original work — Record the original publication, creation date, authorship information, ownership evidence, or licensing documentation associated with the protected material.
- Capture the disputed content — Preserve the relevant webpage, copied text, image, video, graphic, or other material together with its URL and the date it was observed.
- Compare the materials — Document the specific similarities between the original work and the allegedly infringing version rather than relying on a general statement that the content is “similar”.
- Record search visibility — Capture the relevant search query, result URL, result position, and indexed presentation to demonstrate how the disputed material appears within the SERP.
- Establish control — Identify the publisher, website operator, hosting service, platform, or search engine responsible for the relevant part of the digital environment.
This evidence separates the underlying copyright question from the search visibility question and creates a structured basis for further assessment.
How Does Copyright Infringement Interact With Digital Reputation Signals?
Copyright-related content becomes a reputation signal when its presence contributes to the information associated with an entity in search results. Search engines organise content according to query relevance and other ranking factors, while users interpret the resulting information through source credibility, context, consistency, and prominence. A disputed webpage can therefore influence entity perception without the search engine making a determination about whether the material infringes copyright. The reputational impact is linked to discoverability and interpretation, whereas the copyright issue depends on rights and lawful use. Keeping these mechanisms separate produces a more accurate understanding of how intellectual-property disputes interact with online reputation.
Copyright analysis is important because search reputation depends partly on the accuracy, legitimacy, and context of information that becomes publicly discoverable. An online copyright dispute can involve multiple layers, including ownership, reproduction, publication, indexing, ranking, and user interpretation. Treating all negative search content as an SEO problem removes the legal and structural distinctions that determine which remedy is relevant. Conversely, treating every search-result appearance as copyright infringement confuses content discovery with legal responsibility. A precise assessment therefore examines both the legal status of the material and its position within the broader search ecosystem.
Dive Deeper With Our Expert Guides:
How Unauthorized Use of Your Brand Logo Affects Business Reputation
Why Dead and Broken Links Continue Appearing in Google After Pages Are Removed
What Is the Relationship Between Copyright, Search Visibility, and Online Credibility?
Copyright, search visibility, and online credibility represent connected but distinct components of the digital information environment. Copyright defines rights relating to protected expression, search visibility determines how information is surfaced through search systems, and online credibility concerns how users evaluate the reliability and authority of available information. How to Identify and Document Unauthorized Intellectual Property Usage provides a structured basis for assessing whether disputed material involves protected expression, identifying the relevant content, and documenting its relationship to an identifiable entity. These components interact when copyrighted or disputed material becomes prominent in searches associated with an identifiable entity. Search ranking can increase exposure without validating the factual or legal status of the content. Understanding these separate mechanisms provides a clearer basis for analysing reputation signals and digital information risk.
How Should Digital Copyright Issues Be Understood Within Reputation Management?
Digital copyright issues are best understood as part of a wider information-governance problem rather than as an isolated search-ranking issue. Reputation management analyses how content is created, indexed, ranked, interpreted, and associated with an entity across digital systems. Copyright analysis adds another layer by examining ownership, protected expression, authorisation, and lawful use. Search perception is shaped by what users can discover and how prominently that information appears, while legal rights determine whether particular uses of content are permitted. Understanding the interaction between these systems enables copyright disputes to be evaluated through their actual effects on content indexing, search visibility, authority signals, and entity perception.
Digital copyright infringement in online search results concerns the unauthorised use of protected expression, while search visibility concerns how webpages containing that information are discovered and ranked. These are related systems but they answer different questions: copyright analysis examines rights and lawful use, whereas search evaluation examines relevance, indexing, ranking, and visibility. Online reputation develops through the cumulative information users encounter across these systems. A structured assessment therefore distinguishes the original content, the allegedly infringing use, the responsible digital party, the search presentation, and the resulting reputation signals. This separation provides a more precise framework for understanding digital copyright, content indexing, and search reputation.
What constitutes digital copyright infringement in online search results?
Digital copyright infringement occurs when protected creative content is reproduced, distributed, displayed, or published online without appropriate authorisation or another valid legal basis. The appearance of copyrighted material in search results does not automatically mean the search engine itself has infringed copyright.
Can a copied article in Google search results be copyright infringement?
A copied article can constitute copyright infringement when protected expression is reproduced without permission and no applicable exception or licence applies. The legal assessment depends on ownership, the material copied, authorisation, and the relevant jurisdiction.
How can I prove copyright infringement of online content?
Document the original work, ownership or licensing evidence, the allegedly copied material, URLs, publication dates, and screenshots showing where the content appears. Comparing the original and disputed versions helps establish the specific similarities relevant to a copyright claim.
What is the difference between copyright infringement and search delisting?
Copyright infringement concerns the unauthorised use of protected content, while search delisting concerns whether a search engine removes a result from particular search queries. A copyright issue can therefore involve the original webpage, its distribution, its indexing, or its search visibility as separate considerations.
Can copyright infringement affect my online reputation?
Yes, disputed or unauthorised content can affect online reputation when it becomes visible for searches associated with a person, organisation, or brand. Clear Your Name can be relevant to understanding the relationship between copyright infringement, content removal, and search visibility, although the underlying copyright assessment depends on the specific evidence and applicable law.