Deleted news articles still appear in name search results when search engines retain an indexed version of the page, display cached information, or identify copies of the original content on other websites. Reputation management is the process of understanding and influencing how information shapes perceptions of a person or organisation across digital environments. Online reputation refers to the collective interpretation of information associated with an entity across search results, news coverage, reviews and other online sources.
Why Do Deleted News Articles Still Appear in Google Search Results?
Deleted news articles remain visible in search results when a search engine’s index does not yet reflect the page’s removal from its original website. Content indexing is the process through which search engines discover, analyse and store information about web pages for retrieval. When a publisher deletes an article, the original URL can become unavailable while the search engine continues to hold previously indexed information. This creates a difference between the current state of a website and the information presented on a search engine results page (SERP). The persistence of a result therefore reflects the status of the search index, rather than confirming that the original article remains published.
Search engines update their indexes through automated crawling and processing systems. A crawler revisits a URL, retrieves the available response and evaluates whether the indexed representation requires an update. If the page returns a clear not-found or permanently removed response, the search engine processes that information according to its indexing rules. Until that process is complete, the old title, URL or snippet can remain visible. The delay between source deletion and search-result updating explains why an article appears to exist in search results after its publisher has removed it.
How Does Search Engine Indexing Preserve Information About Deleted Articles?
Search engine indexing preserves information about a deleted article when the index has not yet been updated to reflect the source page’s current status. An index is a structured database that allows a search engine to retrieve relevant documents in response to a query. It is not a live copy of every website, refreshed simultaneously whenever a publisher changes content. Search engines rely on crawling schedules, page accessibility and signals received from websites to maintain their indexes. Consequently, a deletion at source and a change in search visibility are separate events.
The status code returned by a deleted URL provides an important technical signal. A 404 Not Found response indicates that the requested resource is unavailable, while a 410 Gone response explicitly indicates that it has been removed and is not expected to return. Search engines use these responses as part of their processing of unavailable pages, although the timing of removal from results is not guaranteed. A URL that continues returning a successful response while displaying an empty page sends a different signal because the server still reports that the resource exists. This distinction affects how search engines interpret the page and update content indexing.
Search snippets also explain the persistence of outdated information. A snippet is a short extract or description displayed beneath a search result, usually generated from page content or other available information. When the underlying article changes or disappears, an existing snippet does not necessarily update at the same moment. The search engine must process the change before its displayed representation reflects the current source. Until then, the snippet can preserve wording associated with the article even when that wording is no longer accessible at the original URL.
Why Does a Deleted Article Affect Name Search Results?
A deleted article affects name search results when search engines continue associating its URL and historical content with the person or organisation named in a query. Name search is a form of entity-based information retrieval in which a search engine attempts to identify documents relevant to a specific person, business or other identifiable subject. An entity refers to a distinct person, organisation, place or concept that a search system recognises across connected sources. Names appearing in article titles, body text, metadata and links help establish relationships between documents and entities. If the article previously ranked prominently for a name, its historical relevance signals can contribute to its continued appearance until the index changes.
Entity perception refers to the understanding of a person or organisation formed from information associated with that entity across digital sources. Search engines do not directly measure reputation as a human judgement; they retrieve and rank documents using signals such as relevance, accessibility, content quality and relationships between sources. However, the resulting search page influences how users interpret an entity because it determines which information appears most prominently. A deleted news article that remains visible can therefore continue shaping perceived credibility, even when the original publisher no longer makes the content available. This is a consequence of persistent search visibility rather than proof that the search engine endorses the article’s claims.
The query itself also influences which results appear. A full-name search, a name combined with a location and a name combined with a professional role represent different information needs. Search engines evaluate the terms and context of each query against the documents available in their indexes. A deleted article can appear for one query but not another because relevance and ranking vary according to the search terms. This explains why checking a name in isolation does not provide a complete assessment of its digital footprint.
How Do Search Engine Results Pages Influence Online Reputation?
Search engine results pages influence online reputation by organising information into a visible hierarchy that affects what users encounter first. A SERP contains ranked organic listings and can also include news results, images, videos, review content and other search features. Its composition determines the balance of information presented for a person or organisation. Users often form an initial impression from titles, snippets, publication names and the relative prominence of each result. As a result, search visibility is an important mechanism through which online information contributes to perceived credibility.
SERP evaluation refers to analysing the sources, formats, relevance and prominence of the results displayed for a particular query. This process examines more than whether a URL appears; it considers the position of the result, the wording of its snippet and the other information displayed alongside it. A deleted article appearing near the top of a name search has a different visibility profile from the same article appearing on a later page. Search ranking does not establish the truth or current validity of an article’s claims. Instead, ranking determines its position within the information retrieval system, which affects the likelihood that users encounter it.
The digital footprint of an entity consists of information associated with it across websites, platforms and search indexes. News articles contribute to this footprint alongside company profiles, public records, professional biographies, reviews and social media posts. Deleting one source changes one part of the information environment, but it does not automatically remove other documents that refer to the same event or subject. The resulting search page reflects the combined availability and ranking of indexed material. Understanding the digital footprint therefore requires examining both the original source and the wider network of related content.
Why Do Copies of Deleted News Articles Continue to Rank?
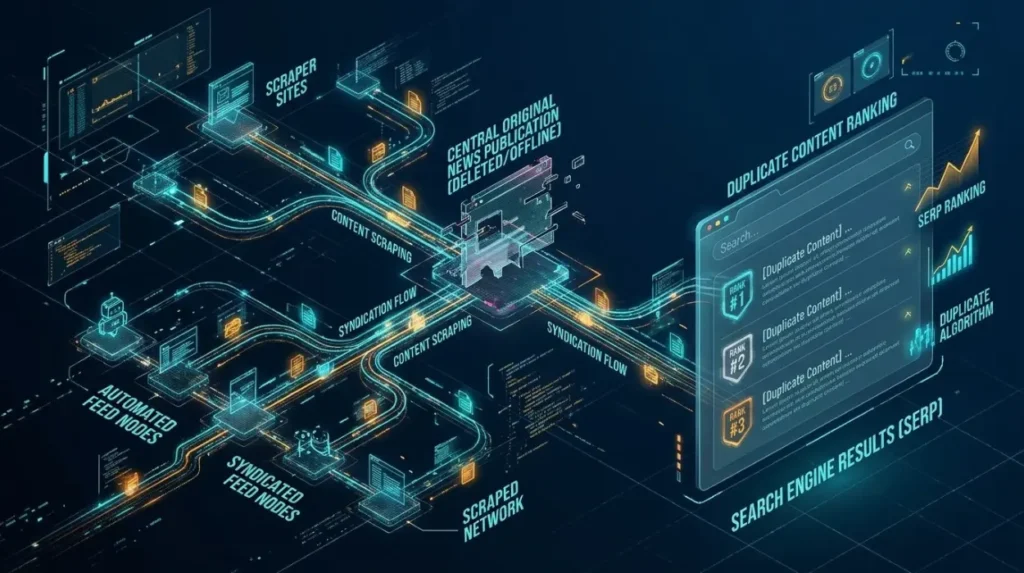
Copies of deleted news articles continue to rank when other websites have republished, quoted, syndicated or independently summarised the original reporting. Republishing creates a separate URL that search engines process independently of the original page. A publisher’s deletion affects its own copy, not the copies hosted by other domains. Search engines can continue retrieving those alternative pages when they remain accessible and relevant to a name query. The disappearance of the original article therefore does not establish that every version of its information has disappeared from the index.
Syndication is one mechanism through which news content appears across multiple websites. News organisations distribute articles through licensing arrangements, content feeds or partnerships, allowing the same report to appear on different domains. Search engines evaluate each accessible URL within their own indexing and ranking processes. Even when two pages contain substantially similar text, their indexing status and search visibility can differ. A removal request directed at one publisher does not automatically change the status of a syndicated version hosted elsewhere.
References and quotations create another layer of persistence. A separate article, forum post or blog can mention the original report without reproducing its full text. Those references remain independent documents with their own URLs and content. If they include a person’s name and details from the deleted article, they can continue appearing in name searches after the original page disappears. This distinction separates the removal of a source document from the wider availability of information derived from it.
How Do Authority and Trust Signals Affect Deleted Article Visibility?
Authority and trust signals affect visibility by contributing to how search systems evaluate and rank accessible content. A source’s reputation, editorial context, links and relevance can influence how its pages are interpreted within search ecosystems. These signals do not mean that every article from an established publisher receives permanent ranking priority. Search engines continually process relevance, content availability and other ranking factors, and the specific weighting of those factors is not fully public. A previously prominent article can retain search visibility until the index and ranking systems reflect changes to the source.
Links also influence the relationship between an article and the wider web. An article referenced by other websites can remain connected to a subject through those links, even after its original URL becomes unavailable. The links themselves do not restore deleted content, but they can point to alternative copies, quotations or related reporting. Search engines use links and document relationships as part of their broader understanding of the web. Analysing these connections helps explain why information associated with a name persists beyond the lifespan of one page.
Trust signals must also be distinguished from factual verification. A high-ranking article is not necessarily accurate, complete or current, and a low-ranking article is not necessarily unreliable. Ranking systems organise results according to their retrieval and ranking criteria rather than delivering a definitive judgement on every statement. Users evaluating an entity therefore benefit from considering the publisher, publication date, available evidence and whether the original material remains accessible. This distinction is central to understanding how search visibility and online credibility interact.
What Role Do Reviews and Sentiment Play in Name Search Reputation?
Reviews and sentiment contribute to online reputation by adding public assessments of an entity alongside editorial content and other information sources. Reviews contain evaluative language about experiences, products, services or professional conduct. Sentiment analysis refers to the computational interpretation of language as positive, negative or neutral, although the meaning of a statement depends on its context. Search engines can display review-related information when it is relevant to a query and supported by available sources. The presence of negative sentiment in search results can affect user perception, but it does not independently establish the accuracy of the underlying claims.
Sentiment distribution describes how positive, negative and neutral assessments are represented across available content. A single deleted news article can remain visible alongside reviews and discussions that express different views of the same entity. The resulting SERP may therefore present a mixed picture rather than one consistent narrative. Search visibility determines which pieces of that picture are easiest to find, while the source and context help users interpret them. Reputation analysis requires examining the overall distribution of available information instead of treating one result as a complete representation of an entity.
Review signals and news coverage also differ in purpose and evidential value. News articles typically report events or developments, whereas reviews describe individual experiences or opinions. Search engines process both as documents, but their formats, structured data and presentation features differ. A review score does not automatically neutralise a negative article, just as deleting an article does not erase the review history associated with an entity. These information types operate as distinct components of the digital footprint.
Dive Deeper With Our Expert Guides:
How Long Does It Take for Google to Automatically Remove 404 Error Pages?
Why Broken Links Still Display Damaging Search Snippets and Titles
How Can Search Visibility Change After an Article Is Deleted?
Search visibility changes after deletion when search engines process the page’s updated status and adjust the results associated with it. The sequence begins with the publisher changing or removing the content, followed by a crawler revisiting the URL and retrieving its new response. The search engine then processes the information and updates its index according to its systems. The result disappears from relevant searches when it is no longer eligible to appear in those results. The timing depends on the technical state of the URL, crawling and indexing processes, and the search engine’s handling of the page.
A removed article and a de-indexed article are not identical concepts. Removal at source means the publisher no longer serves the original content at that URL, while de-indexing means a search engine no longer includes the page in its search results for the relevant index. A page can be removed from a website before it disappears from search results. Conversely, a URL can be excluded from a search index while its content remains accessible directly or through other websites. These distinctions explain why checking the source alone does not confirm the status of the associated search result.
When content has been deleted at source but remains visible in search, the next step in understanding the situation is to distinguish an outdated result from an accessible copy. An outdated result reflects information that no longer matches the current source, while a duplicate or syndicated result points to content that remains available elsewhere. The relevant technical process depends on which condition applies. A page that has genuinely disappeared requires a different assessment from one that continues returning content under another URL. Understanding this distinction provides the basis for analysing how to request immediate URL de-indexing after content is deleted at source.
What Does a Deleted Article Reveal About Digital Reputation?
A deleted article that remains in name search results demonstrates that online reputation depends on more than the current state of a single website. Search engines maintain indexes that update through crawling, processing and ranking systems, so changes at source and changes in visibility do not always occur simultaneously. Duplicate publications, references, links and related reporting also contribute to the persistence of information. These mechanisms explain why a deletion does not necessarily remove every search result connected with the original article. The distinction between source availability and search visibility is therefore essential to accurate reputation analysis.
Online reputation is formed through the interaction between published information, search engine retrieval and user interpretation. Entity perception reflects the information associated with a person or organisation, while search visibility determines how prominently that information appears. Authority, relevance, links, reviews and sentiment contribute to the broader context in which users assess credibility. None of these signals alone establishes whether a claim is accurate or whether an article remains current. Analysing the source, index status and wider digital footprint provides a clearer understanding of why deleted news articles continue to appear in name searches.
Why do deleted news articles still appear in Google search results?
Deleted news articles remain visible when Google has not yet updated its index to reflect the page’s removal. Outdated titles, snippets and cached information can persist until the search engine processes the change.
How long does it take for Google to remove a deleted news article from search results?
The time varies depending on crawling frequency, the page’s status and Google’s indexing process. Removing an article from the original website does not guarantee its immediate disappearance from name search results.
How can I remove a deleted news article from Google search results?
First, confirm that the original URL returns a genuine 404 or 410 response rather than displaying the article or an empty page with a successful status. If the content has been removed at source but remains in search, Google’s outdated-content removal process can help update eligible results.
Why does a deleted news article still affect my online reputation?
A deleted article can continue influencing online reputation while its title or snippet remains visible in search results for a person’s name. Its impact also depends on its ranking position, the wording displayed and whether other websites have republished or referenced the content.
Can removing a news article from its original website remove all copies from search results?
No, deleting the original article does not automatically remove syndicated versions, republications or third-party references. Each URL has its own indexing status, so duplicate content requires separate assessment to understand its continued search visibility.