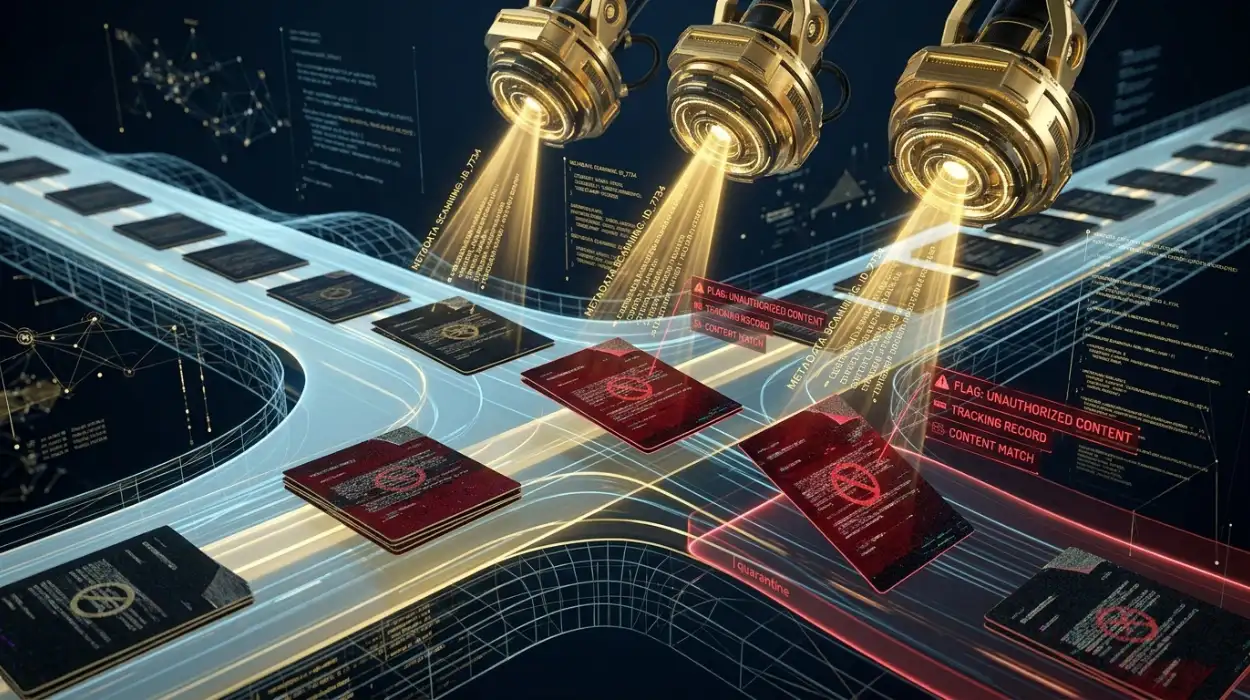
Personal information becomes aggregated when data from separate public and semi-public sources is collected, matched, indexed, and connected to the same individual. Reputation management is the process of understanding and managing information that shapes how an entity is represented across digital environments.
How does personal information become aggregated across the web?
Personal information aggregation is the process of combining data from separate sources into a connected profile of an individual. Online reputation refers to the information and signals associated with an entity across search engines, websites, directories, social platforms, public records, and other digital sources. Each source can contain a limited piece of information, such as a name, location, occupation, contact detail, professional history, or social profile. Data aggregation connects these separate attributes when systems identify relationships between them. The resulting digital footprint therefore contains information that extends beyond any single website.
Aggregation operates through data collection, matching, classification, and redistribution. A directory can publish a professional name, while another source contains an address and a third source contains a social profile. Data providers and search systems can associate these records when names, locations, employment details, usernames, or other identifiers demonstrate a sufficient relationship. Once connected, information can appear across additional databases and websites. This creates a network of references that contributes to entity perception and search visibility.
What types of public sources contribute to a digital footprint?
Public sources contribute different categories of information to an individual’s digital footprint. Search engines index websites, directories, social profiles, news pages, public registers, professional listings, forums, and other accessible content. Data brokers and people-search databases also compile information from public and commercially available datasets. Each source has different collection methods, update schedules, accuracy standards, and publication purposes. These differences affect how information is interpreted when separate records become associated with the same person.
The information itself can include names, previous locations, professional roles, company associations, usernames, public contact details, family associations, property information, and online activity. Not every source contains the same attributes, which means aggregation creates value through combination rather than repetition. One database can fill a gap left by another source, producing a more complete profile. Search engines then encounter a broader information structure when processing queries connected to the individual. This expands the digital footprint beyond information deliberately published by the person.
How do data brokers connect information from different sources?
Data brokers connect information through data collection, record matching, categorisation, and profile construction. A data broker is an organisation that collects or processes information about individuals and provides that information for defined commercial or informational purposes. Matching systems compare identifiers such as names, addresses, telephone numbers, email addresses, employment records, and other attributes. When records demonstrate sufficient similarity, systems associate them with a particular profile. This process creates relationships between information that originally existed in separate datasets.
Data matching also introduces accuracy challenges because identical names and similar attributes can belong to different individuals. An incorrect association can therefore transfer information from one person to another within a compiled profile. Once inaccurate information enters a dataset, subsequent sources can repeat or redistribute it. This creates a feedback pattern where repetition appears to strengthen an association despite the original match being incorrect. Entity resolution therefore represents an important mechanism within personal information aggregation.
How does search engine indexing amplify aggregated information?
Search engine indexing amplifies aggregated information by making content discoverable through queries that connect an individual with specific attributes. Content indexing refers to the process through which search engines discover, analyse, store, and make eligible web content for retrieval. When personal information appears on an indexed page, that page becomes part of the searchable information environment surrounding the entity. Multiple indexed sources create a broader set of references from which search systems interpret the entity. This affects both search visibility and the information encountered by users.
Search engines do not simply display every indexed page in random order. SERP evaluation involves assessing relevance, quality, authority, context, and other ranking signals when determining which results appear for a query. A page containing personal information can therefore become highly visible when it satisfies the intent and ranking conditions of a particular search. Other pages containing related information reinforce the wider context around the entity. Aggregation consequently affects not only how much information exists but also how easily that information can be discovered.
How do search engines interpret connected personal information?
Search engines interpret connected personal information through relationships between entities, attributes, sources, and topics. Entity perception refers to the way an identifiable person, organisation, place, or concept is represented through information available across digital sources. Search systems analyse textual references, structured data, page relationships, links, and contextual associations to understand these entities. The resulting interpretation contributes to how relevant pages are retrieved for searches. This process connects personal information management with broader search visibility dynamics.
Authority and trust signals also affect interpretation. A government register, established professional directory, personal website, social profile, and anonymous forum can contain similar information while carrying different contextual characteristics. Search systems evaluate sources according to factors that influence relevance and quality rather than treating every reference as equally authoritative. Users also apply their own credibility judgements based on source type and consistency. A coherent collection of reliable sources therefore creates a different information environment from a fragmented collection containing contradictory or low-quality references.
Why does information consistency matter across public sources?
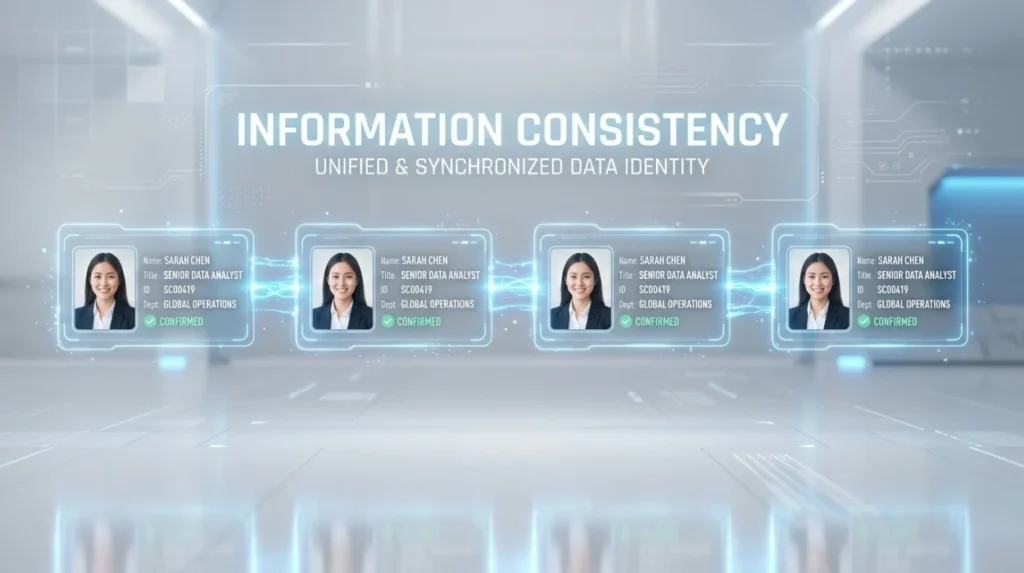
Information consistency matters because conflicting attributes create ambiguity within an entity’s digital footprint. Consistency refers to the alignment of important identifying information across sources, including names, professional details, locations, affiliations, and other relevant attributes. When authoritative sources present compatible information, users receive a clearer representation of the entity. When sources contain contradictory details, search perception becomes more difficult to interpret. Search engines also process these sources independently according to their own indexing and ranking systems.
Consistency does not mean that every source needs identical wording. Different platforms have different purposes, audiences, and content structures. The important factor is whether core entity attributes remain factually aligned across the information ecosystem. Consistent information strengthens contextual relationships, while conflicting information creates competing interpretations. This distinction is particularly relevant when personal information appears across directories, social profiles, public databases, and search results.
How can inaccurate personal information spread across the web?
Inaccurate personal information spreads when one incorrect record is copied, syndicated, matched, or republished by another source. Data aggregation systems frequently rely on existing datasets, which creates pathways for information to move between databases. A single outdated address, incorrect occupation, or mistaken identity association can therefore appear in additional profiles. Search engines then index these separate pages as independent sources even when their underlying information originated from the same dataset. Repetition can create the appearance of confirmation without establishing factual accuracy.
This process is different from independent verification. If multiple websites obtain information from the same underlying database, their agreement does not necessarily represent multiple independent sources. Data provenance refers to the origin and history of information as it moves between systems. Understanding provenance helps distinguish genuine corroboration from duplicated information. This distinction is important when evaluating reputation signals and assessing the reliability of an individual’s digital footprint.
What role do social media profiles play in personal information aggregation?
Social media profiles contribute to aggregation by providing publicly accessible identity attributes, professional information, usernames, photographs, affiliations, interests, and connections. These attributes create contextual signals that can help data systems associate social profiles with other online records. Search engines also index eligible social pages and display them for relevant queries. The result is an additional layer of information connecting an individual to a broader digital identity. Social content therefore forms part of the wider entity representation rather than operating separately from search.
Public profile information also creates relationships between entities. A username can connect a social profile to another website, while an employer reference can connect the profile to a company page. A location can create another relationship between the individual and a geographic entity. These connections provide contextual information that supports entity resolution and search interpretation. The greater the number of reliable connections, the more structured the digital representation becomes.
How do reviews and sentiment affect an aggregated digital profile?
Reviews and sentiment contribute reputation signals by recording opinions, experiences, and evaluations associated with an entity. Sentiment interpretation involves analysing language to identify positive, negative, neutral, or otherwise categorised expressions within content. Search ecosystems can use review information as contextual evidence surrounding an organisation, professional, product, or other entity. The significance of a review depends on its source, relevance, credibility, and relationship to the entity. A single sentiment classification therefore does not independently define overall reputation.
Review content also interacts with other information sources. A professional profile establishes one set of entity attributes, while reviews introduce audience perceptions and experience-based references. Search users encounter these signals together when researching an entity. This creates a combined information environment in which factual identity information and subjective assessments coexist. Reputation analysis therefore requires distinction between verified attributes, opinions, sentiment, and source authority.
How does a full personal information audit identify aggregated data?
A personal information audit identifies where personal information appears, how sources connect, and which data contributes to the broader digital footprint. The audit process examines search results, directories, public databases, social profiles, professional listings, data broker pages, and other relevant sources. It then categorises information according to type, source, visibility, accuracy, and relationship to the individual. This creates a structured view of information that otherwise remains distributed across separate websites. The purpose is to understand the complete information environment rather than inspect one source in isolation.
A structured audit evaluates:
- Identify indexed sources — locate public pages, directories, profiles, databases, and other indexed references containing personal information.
- Classify information types — separate contact details, professional attributes, location data, affiliations, social references, and other identifiable information.
- Trace information relationships — determine how names, locations, employment details, usernames, or other identifiers connect records across sources.
- Evaluate source authority — assess whether information originates from authoritative registers, established platforms, commercial databases, or lower-quality sources.
- Check information accuracy — compare conflicting attributes and identify outdated, duplicated, or incorrectly associated records.
This framework creates the foundation for a full personal information audit across the web by connecting individual sources to the wider information ecosystem. The resulting analysis demonstrates which information is highly visible, which sources appear authoritative, and where conflicting records exist. It also distinguishes between information that is merely available and information that actively contributes to search perception. This distinction makes the audit more useful for understanding digital exposure.
How does aggregated personal information influence online credibility?
Aggregated personal information influences online credibility by shaping the information users encounter when researching an individual. Online credibility refers to the perceived reliability of an entity and the information associated with it across digital sources. Consistent professional information from credible sources provides a coherent basis for evaluating identity and expertise. Contradictory, outdated, or incorrectly associated information creates additional interpretation requirements for users. Search visibility determines which of these signals receive attention first.
Credibility is therefore influenced by both information quality and information prominence. A highly accurate page has limited influence on search perception when it remains difficult to discover, while a prominent inaccurate page can attract significant attention. Search ranking dynamics determine which sources appear prominently for specific queries. Reputation signals then operate within the information that users actually encounter. Personal information aggregation consequently has implications beyond privacy because it also affects entity representation and digital credibility.
How can aggregated information change over time?
Aggregated information changes as source databases update, websites publish new records, profiles change, and search engines recrawl existing pages. A digital footprint is therefore dynamic rather than permanently fixed. Data brokers can update profiles using new information, while public directories can retain historical records after an individual changes circumstances. Search engines also modify their indexes as content changes or becomes unavailable. These processes continually reshape the information environment surrounding an entity.
Historical information remains relevant when it continues to be indexed or referenced by other sources. An outdated page can retain visibility even after the underlying information has changed elsewhere. Conversely, new authoritative sources can introduce current information and alter the contextual balance of search results. Long-term analysis therefore requires monitoring changes in both source content and search visibility. This demonstrates why personal information aggregation is an ongoing digital process rather than a single event.
Dive Deeper With Our Expert Guides:
Why Executives and Founders Face Higher Personal Information Exposure Risks
Why Personal Information Often Appears on Dozens of Sites at Once
Why is understanding personal information aggregation important?
Personal information aggregation is a connected process in which separate records become associated through data collection, matching, indexing, and redistribution. Public directories, social profiles, data brokers, professional platforms, public registers, reviews, and other sources each contribute different reputation signals to the digital footprint. Search engines then evaluate these sources according to relevance, authority, content quality, context, and ranking dynamics. The resulting SERP composition determines which information becomes visible during searches connected to the entity.
Understanding aggregation also requires examining information provenance, source authority, consistency, and accuracy. Repeated information does not automatically represent independent confirmation, while a single authoritative source can carry substantial contextual relevance. A structured audit therefore examines the relationships between sources rather than treating every page as an isolated record. This approach provides a clearer understanding of how personal information becomes connected, indexed, and interpreted across the wider search ecosystem.
How does personal information get aggregated across the internet?
Personal information gets aggregated when data from directories, public records, social media profiles, data brokers, and other sources is collected and matched. These records can then be connected through identifiers such as names, addresses, usernames, employment details, or contact information.
What sources contribute to a person’s digital footprint?
A digital footprint can include social media profiles, professional directories, public registers, data broker databases, review platforms, websites, forums, and news pages. Search engines can index eligible sources, making this information discoverable through relevant searches.
How do data brokers collect personal information?
Data brokers collect information from public records, online sources, commercial datasets, and other available information channels. They combine these records to create profiles containing details such as names, locations, professional information, and online identifiers.
Can inaccurate personal information spread across multiple websites?
Yes, inaccurate information can spread when databases copy, syndicate, or redistribute the same underlying record. Repeated publication does not necessarily confirm accuracy because multiple websites can rely on the same original data source.
What does a personal information audit look for?
A personal information audit identifies where personal data appears online, how different sources are connected, and whether information is accurate, outdated, duplicated, or incorrectly associated. It typically examines search results, directories, social profiles, public databases, and other relevant sources across the digital footprint.