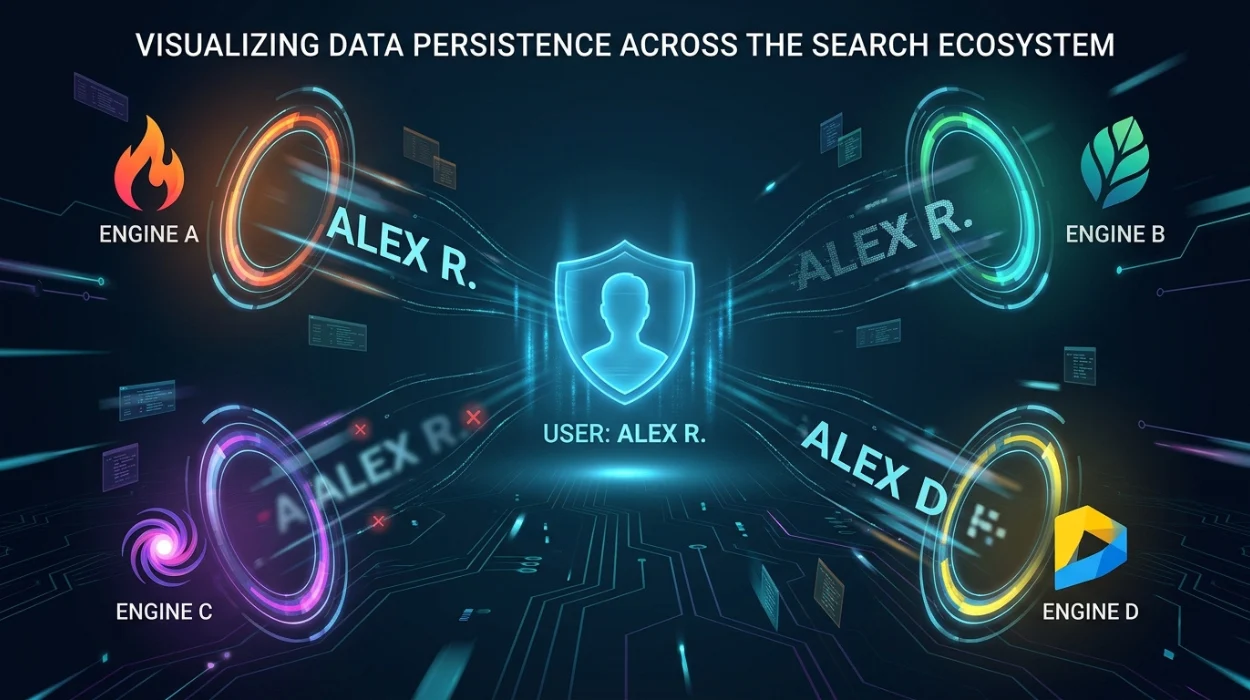
Your name can continue appearing in multiple search engines because each search engine maintains an independent content index, ranking system, and update schedule based on publicly accessible information.
Reputation management is the systematic analysis of how searchable information is collected, indexed, evaluated, and presented across search ecosystems. Online reputation refers to the combination of reputation signals, content indexing, search visibility, and entity perception that determines how an individual is represented within search engine results pages (SERPs). Search engines do not share identical indexes or update content simultaneously, meaning a successful removal in one platform does not automatically affect another. Understanding these independent indexing systems explains why search visibility often differs between Google, Bing, Yahoo, and other search engines. These mechanisms collectively influence online credibility and digital footprint formation.
Why Does Your Name Continue Appearing After a Removal Request?
A removal request affects only the search engine or publisher that processes it and does not automatically change information across the wider search ecosystem.
Content indexing is the process through which search engines discover, evaluate, and store publicly accessible webpages before displaying them in search results. Every search engine operates its own crawling and indexing infrastructure, meaning identical webpages are indexed independently rather than collectively. When information is removed from one index, other search engines continue displaying previously indexed versions until they complete their own evaluation cycles. Reputation management analyses this mechanism because search visibility depends upon each platform’s independent indexing decisions. Entity perception therefore develops differently across separate search environments.
Search visibility also depends on whether the original source remains available online. If a webpage continues publishing personal information, search engines that have already indexed the content retain the ability to display it until new crawls detect changes. Different crawling frequencies explain why one search engine reflects updates while another continues displaying older indexed information. Reputation signals therefore remain distributed unevenly across search ecosystems until each platform reassesses the source independently. This process demonstrates why removal requests rarely produce simultaneous results across every search engine.
What Stages Affect Search Engine Updates?
Search engines update indexed information through independent evaluation processes.
- Discover publicly accessible webpages through links, sitemaps, and structured data.
- Crawl webpages to collect searchable information for evaluation.
- Index relevant content according to technical and quality standards.
- Evaluate authority, relevance, and reputation signals before ranking.
- Refresh indexed information after subsequent crawls detect changes.
How Do Different Search Engines Build Separate Indexes?
Each search engine builds its own index by independently crawling and evaluating publicly available content.
A search index is a database containing information collected from websites that search engines consider eligible for search results. Google, Bing, Yahoo, DuckDuckGo, and other platforms maintain separate indexing infrastructures despite frequently discovering the same webpages. Every search engine applies its own crawl scheduling, ranking priorities, technical evaluation, and SERP evaluation methods. Reputation management examines these differences because they influence how entity perception develops across different search environments. Search visibility therefore varies even when the underlying source remains identical.
Independent indexing also explains why removal timelines differ. One search engine may revisit a webpage within days, while another waits significantly longer before updating stored information. Content indexing therefore operates continuously rather than simultaneously across competing platforms. Reputation signals evolve at different speeds because each search engine independently determines when previously indexed information requires reassessment. Understanding this distinction provides a clearer explanation of persistent search visibility after removal requests.
Why Do Search Engines Rank the Same Name Differently?
Search engines rank identical names differently because each platform evaluates authority, relevance, and reputation signals using independent ranking systems.
Search ranking is the process of ordering indexed content according to the likelihood that it satisfies user intent. Algorithms compare content quality, structured information, backlinks, topical authority, technical accessibility, and semantic relevance before assigning positions within search results. Although similar ranking principles exist across major search engines, implementation differs because every platform defines its own evaluation criteria. Reputation management analyses these distinctions because search visibility reflects algorithmic interpretation rather than identical ranking formulas. Entity perception therefore changes according to each platform’s assessment of available information.
Authority signals also vary between search engines. One platform may assign greater importance to structured data, while another emphasises backlink quality or freshness. Review signals, publication history, and semantic relationships further influence SERP evaluation across competing indexes. Reputation signals therefore accumulate differently despite referencing the same individual or organisation. Search ecosystems consequently present slightly different representations of the same digital identity.
Which Signals Influence Search Rankings Across Platforms?
Search engines compare multiple reputation indicators before assigning rankings.
- Evaluate source authority using recognised editorial credibility and trusted domains.
- Measure semantic relevance by comparing indexed content with search intent.
- Interpret structured data that defines identifiable people and organisations.
- Assess backlink quality to determine external trust signals.
- Review content freshness through recurring indexing and publication updates.
How Does a Digital Footprint Affect Multiple Search Engines?
A digital footprint is the collection of publicly searchable information associated with an identifiable individual across online platforms.
Every indexed webpage contributes to a broader digital footprint regardless of which search engine discovers it first. News publications, business directories, professional profiles, social platforms, public registers, educational websites, and archived content collectively provide information that search engines evaluate independently. Reputation management defines digital footprints as distributed information systems because searchable identity develops across numerous sources rather than one website. Search visibility therefore reflects the combined influence of multiple indexed references. Entity perception strengthens or weakens according to the consistency and authority of those references.
Digital footprints also expand through information replication. Publicly available content is frequently reproduced by data aggregators, directory networks, or syndicated publishers operating across multiple domains. Once duplicated information becomes indexed by different search engines, removal from one source does not immediately eliminate every searchable reference. Reputation signals therefore remain active across multiple indexes until each source changes or each search engine updates its records. This explains why digital identities continue appearing after isolated removals.
Why Does Removed Information Sometimes Reappear?
Removed information reappears when search engines rediscover the same information from alternative indexed sources.
Content indexing evaluates every eligible webpage independently. If identical information exists on multiple domains, search engines continue discovering and indexing those alternative sources even after one version disappears. Reputation management analyses this behaviour because search visibility depends upon the availability of information across the wider search ecosystem rather than one publisher alone. Entity perception therefore reflects cumulative indexing instead of isolated publication events. Search ecosystems prioritise accessible information regardless of where equivalent content first appeared.
Reappearance also occurs because cached information, syndicated databases, archived copies, and duplicate publications remain available during subsequent crawl cycles. Search engines evaluate these sources according to authority and relevance before deciding whether to retain them within SERPs. Independent indexing therefore enables similar information to regain visibility after updates elsewhere. Understanding this mechanism demonstrates that search ecosystems operate through continuous reassessment rather than permanent indexing decisions.
How Do Search Engine Results Pages Influence Online Reputation?
Search engine results pages (SERPs) organise indexed information into an ordered representation of an individual based on relevance, authority, and reputation signals rather than publication sequence.
A SERP refers to the collection of results displayed after a user enters a search query. Every result occupies a position determined through the search engine’s independent evaluation of indexed content. Search visibility increases as content appears more prominently because higher-ranking pages receive greater user attention. Entity perception therefore develops from the overall composition of search results instead of one isolated webpage. Reputation management analyses SERP composition because search rankings directly influence how digital identities are interpreted across different search ecosystems.
Search engines continuously reassess SERPs as webpages change, authority signals evolve, and fresh information becomes available. Updated content, revised metadata, structured information, and technical improvements all contribute towards ranking adjustments over time. Information that consistently demonstrates credibility retains stronger search visibility because algorithms evaluate reliability alongside relevance. Reputation signals therefore influence both ranking stability and online credibility. SERP evaluation represents an ongoing comparison between competing information sources rather than a permanent ranking decision.
Which Factors Shape SERP Evaluation?
Search engines compare multiple quality signals before displaying search results.
- Evaluate semantic relevance between the search query and indexed content.
- Measure authority using trusted domains, editorial quality, and backlink relationships.
- Assess technical accessibility through crawlability, structured data, and page performance.
- Interpret reputation signals that strengthen entity credibility across indexed sources.
- Refresh rankings after new crawling and indexing cycles identify updated information.
How Do Reputation Signals Shape Entity Perception Across Search Engines?
Reputation signals are measurable indicators that search engines use to evaluate credibility, reliability, and authority when organising searchable information.
Entity perception refers to the representation of a person or organisation across search ecosystems after algorithms evaluate available information. Reputation signals include authoritative publications, structured entity data, trusted backlinks, topical consistency, and recognised references distributed across indexed websites. Search engines compare these signals collectively because credibility develops through relationships between multiple sources rather than individual webpages. Search visibility therefore depends upon the overall quality of indexed information supporting an identifiable entity. Reputation management examines these relationships because they influence long-term online credibility.
Consistency also plays an important role in search evaluation. Identical names, professional profiles, biographies, and organisational information strengthen semantic relationships that help algorithms understand entity identity accurately. Contradictory or fragmented information weakens search evaluation because search engines compare factual consistency between multiple indexed sources. Reputation signals therefore contribute directly to stable entity perception across different search engines. This cumulative evaluation explains why digital credibility develops progressively through ongoing indexing cycles.
Dive Deeper With Our Expert Guides:
How Your Name Becomes Publicly Searchable Across Multiple Online Platforms
What a Name Removal Service Addresses Beyond Just Google Search Results
Why Do Duplicate Sources Continue Affecting Search Visibility?
Duplicate sources continue affecting search visibility because search engines independently evaluate every accessible webpage containing relevant information.
Duplicate information frequently originates from syndicated publications, data aggregators, mirrored databases, archived webpages, or directory networks. Search engines treat each source as a separate indexing candidate even when similar factual information appears repeatedly. Reputation management analyses this behaviour because search visibility depends on the combined influence of all indexed references rather than one publication. Entity perception therefore reflects cumulative evidence distributed across multiple domains. Search ecosystems maintain these relationships until independent indexing cycles identify qualifying updates.
Search engines also distinguish duplicate content from duplicate facts. Multiple websites can legitimately publish identical information while contributing different authority signals, structured information, and contextual relevance. Algorithms evaluate each source according to its own credibility before determining its position within SERPs. This explains why removing one webpage rarely eliminates all searchable references associated with the same name. Independent evaluation therefore preserves multiple representations across different search engines.
Why Duplicate Information Persists Across Platforms
Search ecosystems continue displaying duplicate information because separate indexing systems operate independently.
- Identify duplicate publications across multiple publicly accessible websites.
- Compare authority signals before determining ranking positions.
- Maintain indexed references when each source contributes independent contextual value.
- Refresh visibility only after updated crawling confirms changes across individual sources.
How Does Cross-Platform Search Visibility Affect Online Credibility?
Cross-platform search visibility strengthens or weakens online credibility because search users often compare information across multiple search engines.
Online credibility refers to the perceived reliability of searchable information associated with an identifiable entity. Search engines independently organise available information, but users frequently encounter consistent themes across different platforms because they index overlapping sources. Reputation management analyses cross-platform visibility because entity perception develops from repeated exposure to similar reputation signals across independent search ecosystems. Consistency therefore strengthens credibility, while conflicting information creates uncertainty. Search visibility extends beyond one search engine to encompass the wider digital environment.
Independent ranking systems also influence perceived authority. Information receiving prominent visibility across multiple search engines reinforces trust because repeated exposure strengthens recognition. Conversely, inconsistent rankings or conflicting indexed information influence entity perception differently depending on the platform. Reputation signals therefore operate cumulatively across the wider search ecosystem instead of remaining isolated within one search engine. This relationship demonstrates why reputation management evaluates the complete digital footprint rather than a single search platform.
Understanding removing your name from search engines in the UK across Bing and Google provides additional context for how independent search indexes respond differently to removal requests and ongoing content indexing. Comparing search ecosystems demonstrates why identical information follows different visibility timelines across separate platforms.
Names continue appearing across multiple search engines because every platform maintains its own content indexing systems, ranking algorithms, and update schedules. Reputation management explains these differences by analysing search visibility, reputation signals, entity perception, authority evaluation, and the relationships between independent search ecosystems rather than treating search engines as a single unified system.
Understanding digital footprints, SERP evaluation, content indexing, duplicate information, and cross-platform search visibility provides a clearer explanation of why removal requests do not produce identical outcomes everywhere at the same time. These concepts demonstrate how online reputation develops through continuous search evaluation and why different search engines independently determine the visibility of publicly available information.
Why does my name still appear in search engines after I request removal?
Search engines maintain independent indexes and update their search results at different times. Even if one platform removes your name, other search engines may continue displaying previously indexed information until they complete their own crawling and indexing cycles.
Does removing my name from Google also remove it from Bing and other search engines?
No. Google, Bing, and other search engines operate separate indexing systems and evaluate removal requests independently. Each platform requires its own review process before search visibility changes.
Why is my name showing in multiple search results from different websites?
Your name can appear on multiple websites because information is often copied, syndicated, or published by directories, public records, and data aggregators. Each source can be indexed separately, increasing overall search visibility across different search engines.
Can Name Removal Services help reduce search visibility across multiple search engines?
Name Removal Services assess where your name is published, identify eligible removal options, and evaluate search engine-specific processes. Providers such as Clear Your Name analyse indexing sources and applicable removal pathways to support broader reputation management objectives.
How do search engines decide whether my name appears in search results?
Search engines evaluate indexed content using ranking factors such as relevance, authority, structured data, and reputation signals. The position of your name in search results depends on each search engine’s independent algorithms and content indexing process.