A personal information removal service can be evaluated through its source coverage, removal methodology, evidence standards, monitoring process, scalability, and ability to distinguish source-level removal from search-result change. Reputation management strategies differ based on whether they remove unwanted information, suppress existing content, or strengthen alternative reputation signals.
Online reputation control methods are evaluated through their effect on search visibility, reputation signals, entity credibility, risk exposure, and long-term sustainability. Personal information removal sits within this wider system because exposed names, addresses, contact details, employment records, and other identifiers can influence the digital footprint associated with an individual. Evaluating the method rather than simply the promised outcome provides a clearer basis for comparing available approaches.
How does personal information removal compare with content suppression?
Personal information removal and content suppression address reputation exposure through different mechanisms. Removal operates by attempting to make the originating information unavailable, restricted, corrected, or de-indexed, while suppression operates by influencing the composition of search results so that unwanted content receives less visibility. Removal therefore targets the underlying source or access pathway, whereas suppression focuses more directly on SERP composition. These approaches can overlap but do not produce the same technical outcome.
Removal provides a source-level intervention when a website or platform accepts a valid request and changes the underlying content. Suppression does not necessarily alter the original webpage and instead relies on competing content, relevance, authority, and ranking relationships. The distinction affects risk exposure because suppressed information can remain publicly accessible even when its search position changes. Evaluating these approaches therefore requires separate measurements for source accessibility and search ranking influence.
How does content creation compare with personal information removal?
Content creation strengthens the information environment around an entity, while personal information removal attempts to reduce exposure to specific unwanted information. Content enhancement operates by introducing relevant, authoritative material that search engines can associate with the entity. Removal operates by addressing a particular source or data record under an applicable policy or procedural mechanism. One approach adds or strengthens information; the other seeks to reduce the availability of existing information.
The effectiveness of content creation depends on relevance, authority, indexing, quality, and sustained publication. Its influence on SERP composition is therefore indirect and dependent on how search systems evaluate competing pages. Removal has a more direct relationship with the targeted information when the originating source accepts the request. However, removal does not automatically create replacement information or establish a stronger reputation signal elsewhere, making the two approaches functionally different.
How should source-level removal and search-result removal be evaluated?
Source-level removal and search-result removal need separate evaluation because they operate at different points in the search ecosystem. Source-level removal changes the availability of information at the originating website or database. Search-result removal changes whether a particular URL or information category appears through a search engine for specified queries. A search-result change does not necessarily mean that the underlying webpage has been deleted.
This distinction affects measurement accuracy. A provider can report a source-level outcome by verifying whether the original URL remains accessible, while search visibility requires query-based monitoring of indexed results. A reliable evaluation framework therefore records both states independently. Treating them as one outcome can obscure persistent exposure through duplicate sources, alternative URLs, archived records, or other indexed pages.
How does an organic approach compare with a reactive removal approach?
An organic approach builds or strengthens reputation signals over time, while a reactive removal approach responds to specific instances of unwanted information. Organic reputation management operates through sustained content development, authoritative references, consistent entity information, and positive or neutral search signals. Reactive removal operates by identifying an existing problem and addressing its source through an appropriate reporting or correction mechanism. Their timelines, resource requirements, and measurable outcomes differ.
Organic methods tend to address the broader information environment rather than a single URL. Their impact depends on continued indexing, content relevance, authority, and ranking relationships. Reactive removal has a narrower scope because it focuses on a defined piece of information and its originating source. This makes the approaches difficult to compare through a single performance indicator because one measures ecosystem development while the other measures source intervention.
Which factors determine the effectiveness of a personal information removal method?
Effectiveness is determined by the match between the information, the responsible source, the applicable policy, the evidence supplied, and the requested action. A removal request has a stronger procedural basis when the reported content clearly falls within the relevant platform or website criteria. Evidence establishes the connection between the individual, the information, the source, and the reason for the request. Accurate classification therefore forms a central part of the removal mechanism.
Effectiveness also depends on whether the information exists elsewhere. A successful removal from one website does not establish that the same information has disappeared from other domains or databases. Duplicate records can preserve the same reputation signal within the digital footprint. Evaluation therefore needs to measure both the outcome for the targeted source and the persistence of equivalent information across the wider search ecosystem.
How important is source coverage when evaluating removal services?
Source coverage measures how comprehensively a removal process identifies websites, directories, databases, people-search platforms, and other properties containing relevant personal information. A narrow approach can address one known URL without examining related sources. A broader approach maps the information environment around an individual by identifying repeated names, contact details, addresses, usernames, or associated records. Coverage therefore influences the completeness of the exposure assessment.
Source coverage also affects scalability. A process that relies entirely on manual identification can become resource-intensive as the number of sources increases. Structured discovery methods can make recurring searches more consistent by using defined identifiers and search patterns. The important evaluation point is not the number of sources claimed but whether the methodology identifies relevant exposure systematically and records each source accurately.
How does evidence quality affect the comparison between providers?
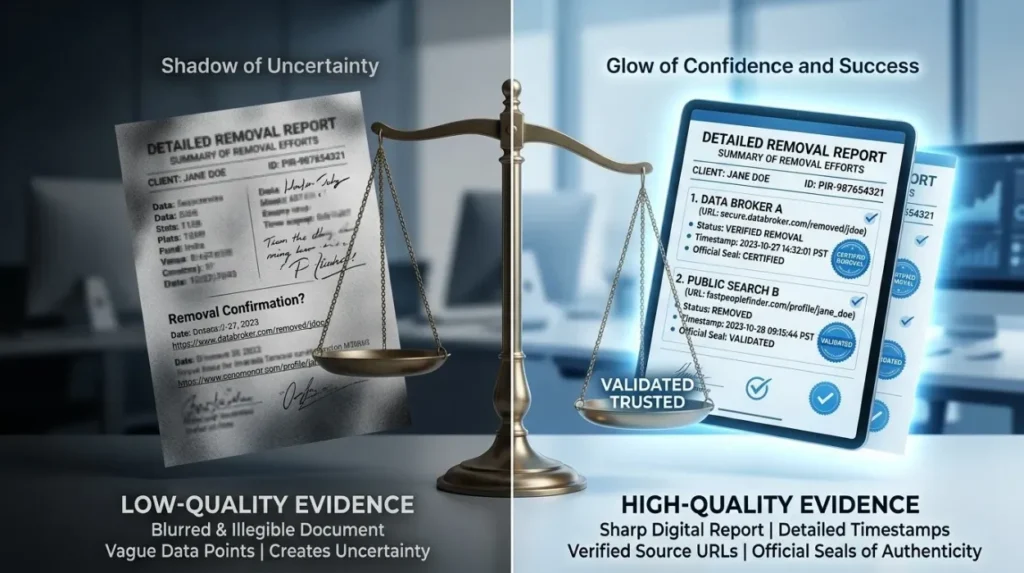
Evidence quality provides a measurable basis for comparing removal methodologies because it shows how a provider establishes the factual and procedural basis for each request. Strong evidence identifies the exact URL, information displayed, relevant identity connection, applicable policy, and requested outcome. Weak evidence can blur the distinction between personal information, criticism, public records, and other content categories. The quality of classification directly affects the clarity of the removal request.
A structured evidence process also improves consistency across repeated submissions. Each case can be documented according to the same criteria, making outcomes easier to monitor and analyse. This creates an auditable relationship between the reported content and the platform’s response. From a reputation management perspective, evidence quality therefore contributes to risk control as well as procedural accuracy.
How do search engines interpret reputation signals after information changes?
Search engines interpret reputation signals through the wider information environment associated with an entity. Crawling, indexing, retrieval, ranking, and entity association processes determine which information becomes visible for relevant queries. A change to one webpage does not automatically change every signal associated with the same individual. Search ranking influence therefore depends on the remaining indexed information and the relationships between sources.
When personal information disappears from a source, the available information set changes. Search engines then process the updated state through their own systems, while duplicate or related sources can continue generating similar signals. This explains why source-level action and SERP composition can change at different rates. Evaluation needs to distinguish between the removal event and its subsequent search visibility effect.
How do short-term and long-term impacts differ?
Short-term impact concerns the immediate status of a targeted source or search result, while long-term impact concerns whether unwanted information remains absent and whether related exposure reappears. A short-term source change can be measured through accessibility checks immediately after an action. Long-term evaluation requires recurring monitoring because information can be republished, reproduced, or discovered on another domain. Sustainability therefore involves persistence rather than a single successful event.
Long-term reputation effects also depend on the broader SERP environment. Removing one result can change one component of a search query without transforming the entire entity profile. New information, existing authoritative sources, reviews, professional references, and duplicate records can continue influencing entity perception. A sustainable approach therefore monitors both the original target and the surrounding information environment.
Dive Deeper With Our Expert Guides:
How to Improve Your Chances of a Successful Personal Data Removal
How to Request Removal of Personal Data From Public Registers
How does risk exposure differ between removal and suppression strategies?
Removal and suppression carry different forms of risk because they operate through different mechanisms. Removal targets a specific information source and depends on the source’s rules, evidence requirements, and decision process. Suppression leaves the original information available while attempting to alter its position or prominence within search results. The underlying content therefore remains an exposure point under a suppression model.
Risk evaluation needs to consider accessibility, persistence, duplication, indexing, and discoverability. A suppressed page can remain accessible through direct URLs, alternative queries, or other search engines. A removed page can also have duplicates elsewhere, creating a separate exposure pathway. These differences demonstrate why removal and suppression require distinct monitoring criteria rather than one combined measurement.
How scalable is a personal information removal approach?
Scalability refers to the ability to identify, process, document, and monitor an increasing number of information sources without reducing procedural consistency. Personal information exposure can involve multiple websites, directories, databases, and search results, creating a repetitive workload. A scalable approach uses structured source identification, standardised evidence records, defined reporting procedures, and repeatable monitoring. These mechanisms reduce inconsistency as the number of sources increases.
Scalability also involves prioritisation. Sources with direct identifying information, high search visibility, strong entity associations, or repeated publication patterns can receive separate tracking categories. This does not mean that every source has the same reputation impact. Instead, categorisation creates a consistent method for analysing source importance and allocating monitoring effort.
What should a provider’s monitoring framework measure?
A monitoring framework needs to measure source accessibility, search visibility, duplicate exposure, indexing status, and persistence over time. Source accessibility establishes whether the original information remains available. Search monitoring establishes whether the affected URL or equivalent information continues to appear for relevant queries. Duplicate monitoring identifies whether the same reputation signal has migrated to another source.
A practical evaluation framework can therefore include the following steps:
- Identify source status — verify whether each reported URL remains live, restricted, corrected, or deleted after the relevant action.
- Measure SERP visibility — record whether the affected page continues appearing for relevant personal-name or identifying queries.
- Compare duplicate sources — examine related domains for substantially equivalent information that continues to expose the same personal details.
- Track indexing changes — distinguish a source-level modification from its later processing within search-engine indexes.
- Review persistence — compare observations over defined intervals to determine whether the information remains unavailable rather than temporarily disappearing.
This framework separates measurable outcomes from assumptions about reputation improvement. It also provides a consistent basis for comparing removal approaches that operate at different stages of the information ecosystem.
How should long-term sustainability be assessed?
Long-term sustainability is assessed by examining whether the removal outcome persists, whether duplicate information remains available, and whether new exposure appears over time. A process that achieves a temporary source change without monitoring provides limited information about continuing risk. Sustainable evaluation therefore treats monitoring as an ongoing measurement function rather than a final administrative step. The objective is to establish whether the original exposure remains resolved within the observed search ecosystem.
Sustainability also depends on the nature of the underlying information. Some records originate from databases that regularly update or republish information, while other pages represent isolated publications. The likelihood of recurring exposure therefore relates to source structure and information propagation. Understanding these mechanisms helps distinguish a durable source intervention from a temporary change in search visibility.
How can the overall evaluation be connected to a final provider decision?
A final evaluation needs to compare methodology, evidence standards, source coverage, monitoring, scalability, risk exposure, and sustainability rather than relying on a single promised outcome. Each criterion measures a different part of the information-removal process. Methodology explains how sources are handled, evidence standards explain how requests are supported, and monitoring explains how outcomes are verified. Together, these criteria provide a structured basis for assessing how an approach fits a particular digital footprint.
The decision process also needs to distinguish personal information removal from broader reputation management. Removal addresses specific information exposure, while content enhancement and suppression influence the wider composition of search results. A trusted personal information removal service therefore needs to be assessed according to the mechanism it actually applies, the evidence supporting that mechanism, and the outcomes it measures. This keeps the evaluation grounded in observable processes rather than general reputation claims.
Personal information removal services can be evaluated by comparing their source coverage, evidence handling, procedural methodology, monitoring systems, scalability, risk exposure, and long-term sustainability. Removal differs from suppression because it targets the availability of information, while suppression focuses on search visibility without necessarily changing the underlying source. Content creation also operates differently because it strengthens alternative reputation signals rather than directly addressing the original information.
The distinction between source-level outcomes and SERP composition remains central to effective evaluation. A source can change without an immediate search-result change, while a search-result change can occur without deletion of the underlying information. Organic and reactive approaches also differ in timescale, scope, and measurement requirements. A structured evaluation therefore considers the specific mechanism being used, the evidence supporting it, the information ecosystem surrounding the target, and whether the resulting change remains sustainable over time.
How do you evaluate a personal information removal service before choosing one?
Check whether the service explains its removal process, target data brokers, privacy safeguards, evidence requirements, and monitoring methods. A reliable personal information removal service should clearly state what data it can target and what limitations apply.
What should I look for in a personal data removal service?
Look for clear coverage of people-search sites, data brokers, public directories, and other sources that expose personal details. Also review how the service handles sensitive information, removal requests, follow-up checks, and changes in data listings.
How can I tell if a personal information removal service is legitimate?
Review its published process, privacy policy, terms, service scope, and explanation of how removal requests are submitted. Clear Your Name can be assessed using the same criteria, including transparency about what the service can and cannot remove.
Does a personal information removal service remove data permanently?
Removal is not always permanent because information can reappear when databases refresh or new records are created. Effective personal data removal involves follow-up monitoring and repeat requests where necessary.
How much does a personal information removal service usually do for you?
Services can handle tasks such as identifying exposed personal details, submitting removal requests, tracking responses, and monitoring selected sources. The exact coverage depends on the provider, the websites targeted, and the type of information being removed.